Find where the gap to your rivals lives.
FleetEdge Team Diagnostic · Beta
Where does the gap to the boats you race live — in the boat, in the conditions, or in how you sailed?
You get: a private season view of your boat’s evaluated pace, the conditions it met and its crew residual, event by event, against the rivals you pin.
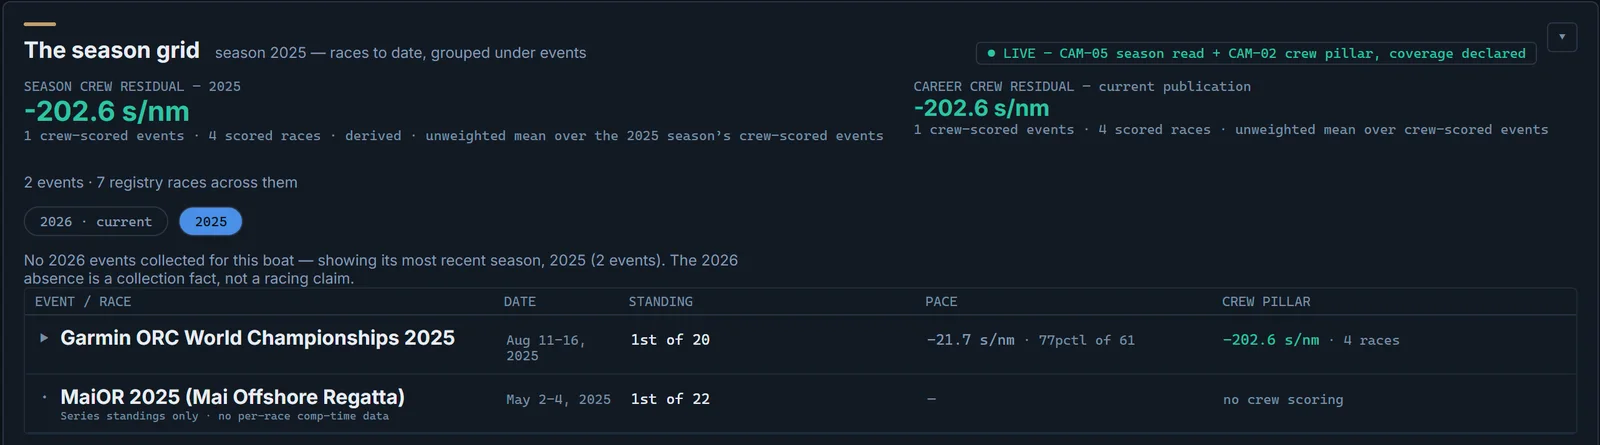
Beta — access by request · The screen is a real campaign on published race results.
Read your boat’s evaluated pace, the conditions it met and how it was sailed, side by side — a private diagnostic for your campaign.
For racing teams, tacticians, campaign managers, and coaches. Access by request.
Universe: one boat — yours Story: ORC Worlds 2025, Tallinn Private to your team
The sample, the limits and the next step
See a sample: the demonstration campaign below, on published race results.
The limits: one boat — yours, visible to your team only; no on-board telemetry. The crew residual is a model-adjusted residual that helps investigate execution: the performance that remains after the boat’s evaluated pace and the measured conditions are accounted for. It is not a verdict on the crew alone.
Next: request an anonymized diagnostic sample, or beta access — the product opens once your access is granted.
Beta — access by request · The product is running: the screens below are a real campaign on the live corpus, in beta. Every panel carries the product’s own status label — LIVE, UNDER VALIDATION, or PLANNED — in the screen itself; a panel’s label governs its claims.
The campaign view, live.
A season on one screen: the crew-pillar headline, every collected event with its standing and pace, the improvement queue, and the rivals you pinned. The screens below are our own demonstration campaign on published race data — customer campaigns stay private to their teams.
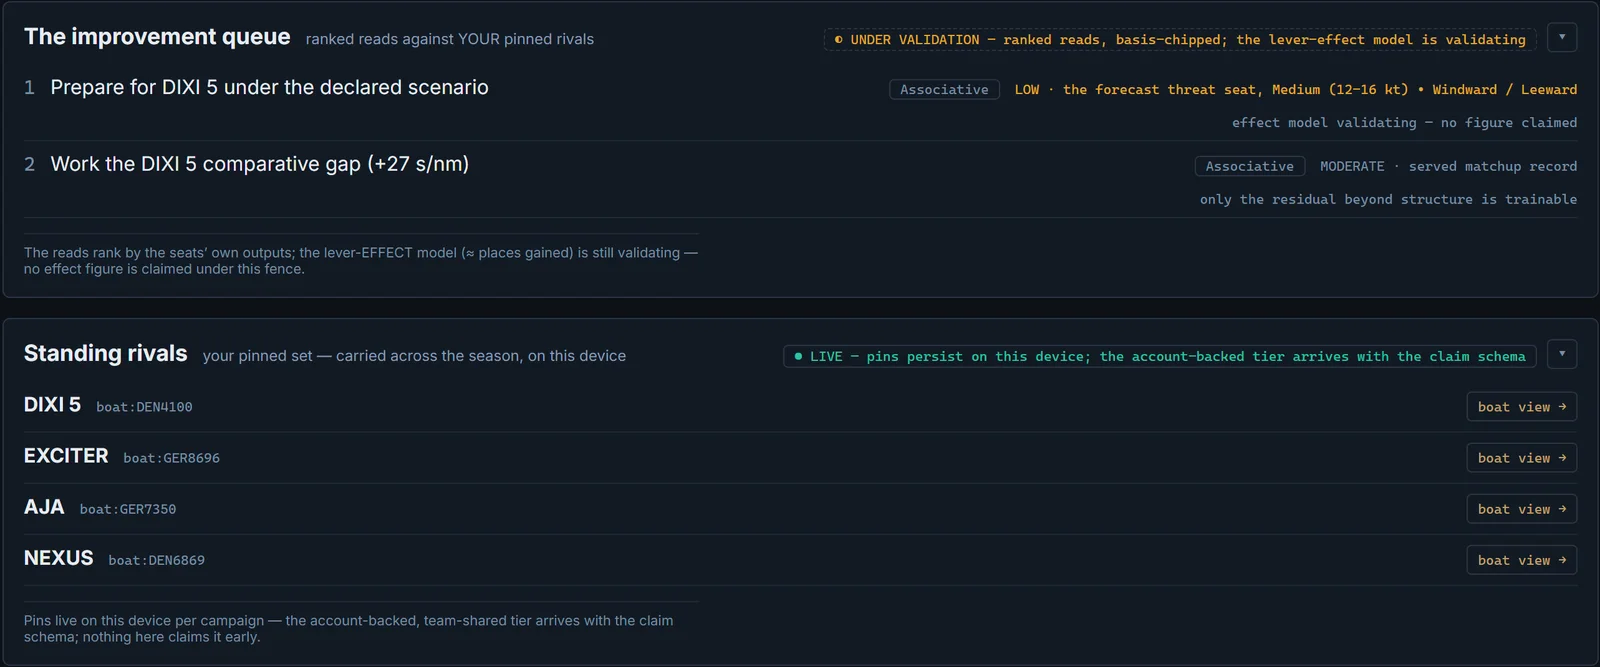
The field, placed and decomposed.
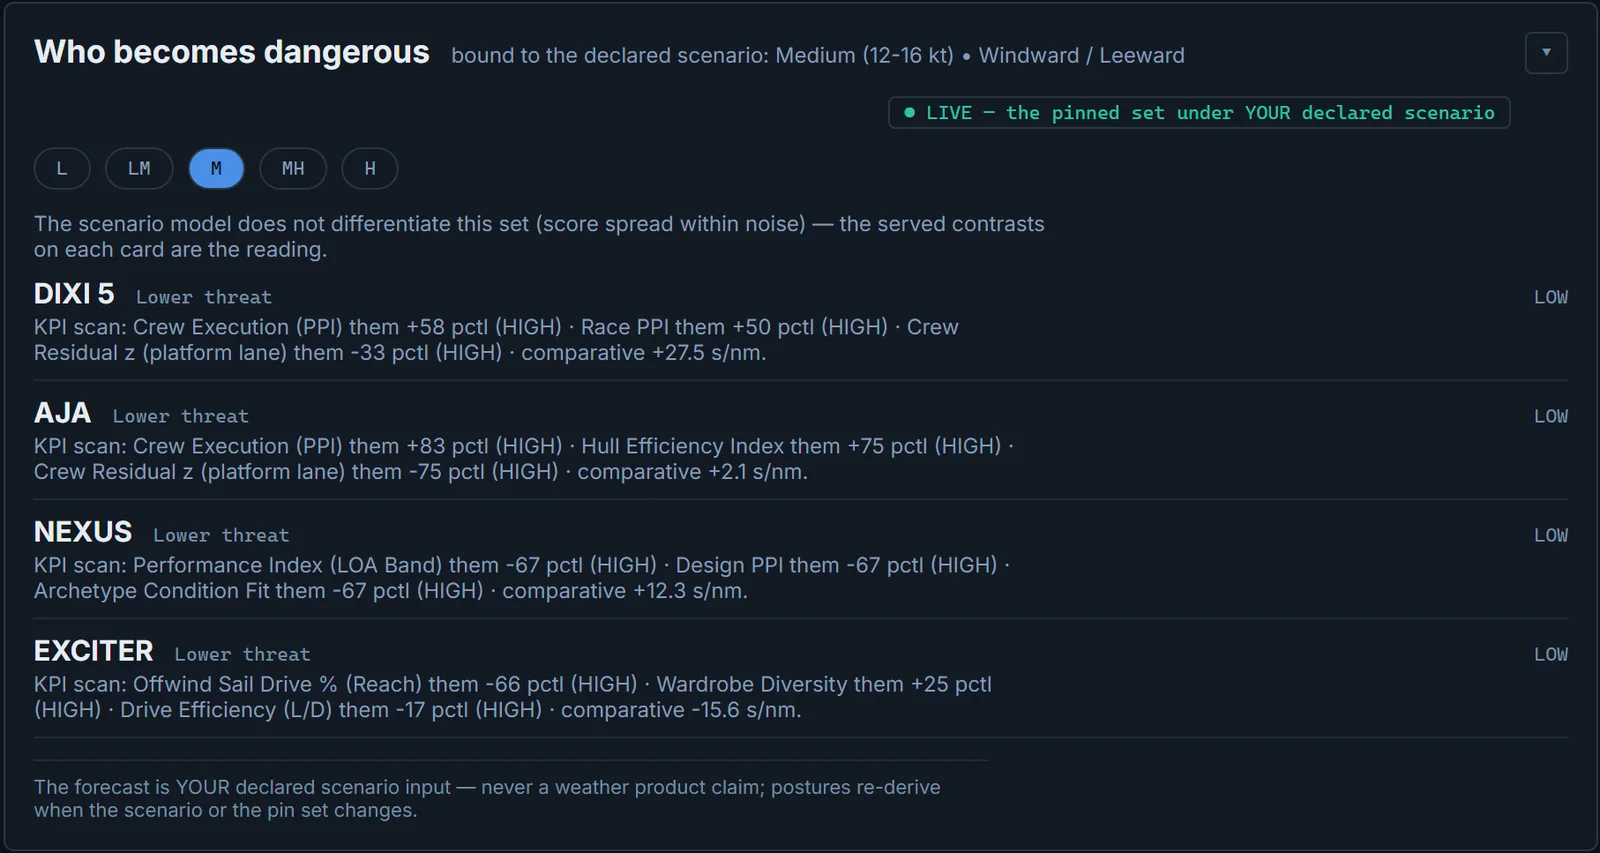
Pick a dimension and the board ranks your field around you — green is better, not higher, and confidence rides every row. Each pinned rival gets a paired contrast card composed from the published results, and the threat panel re-reads the pinned set under your declared forecast band.
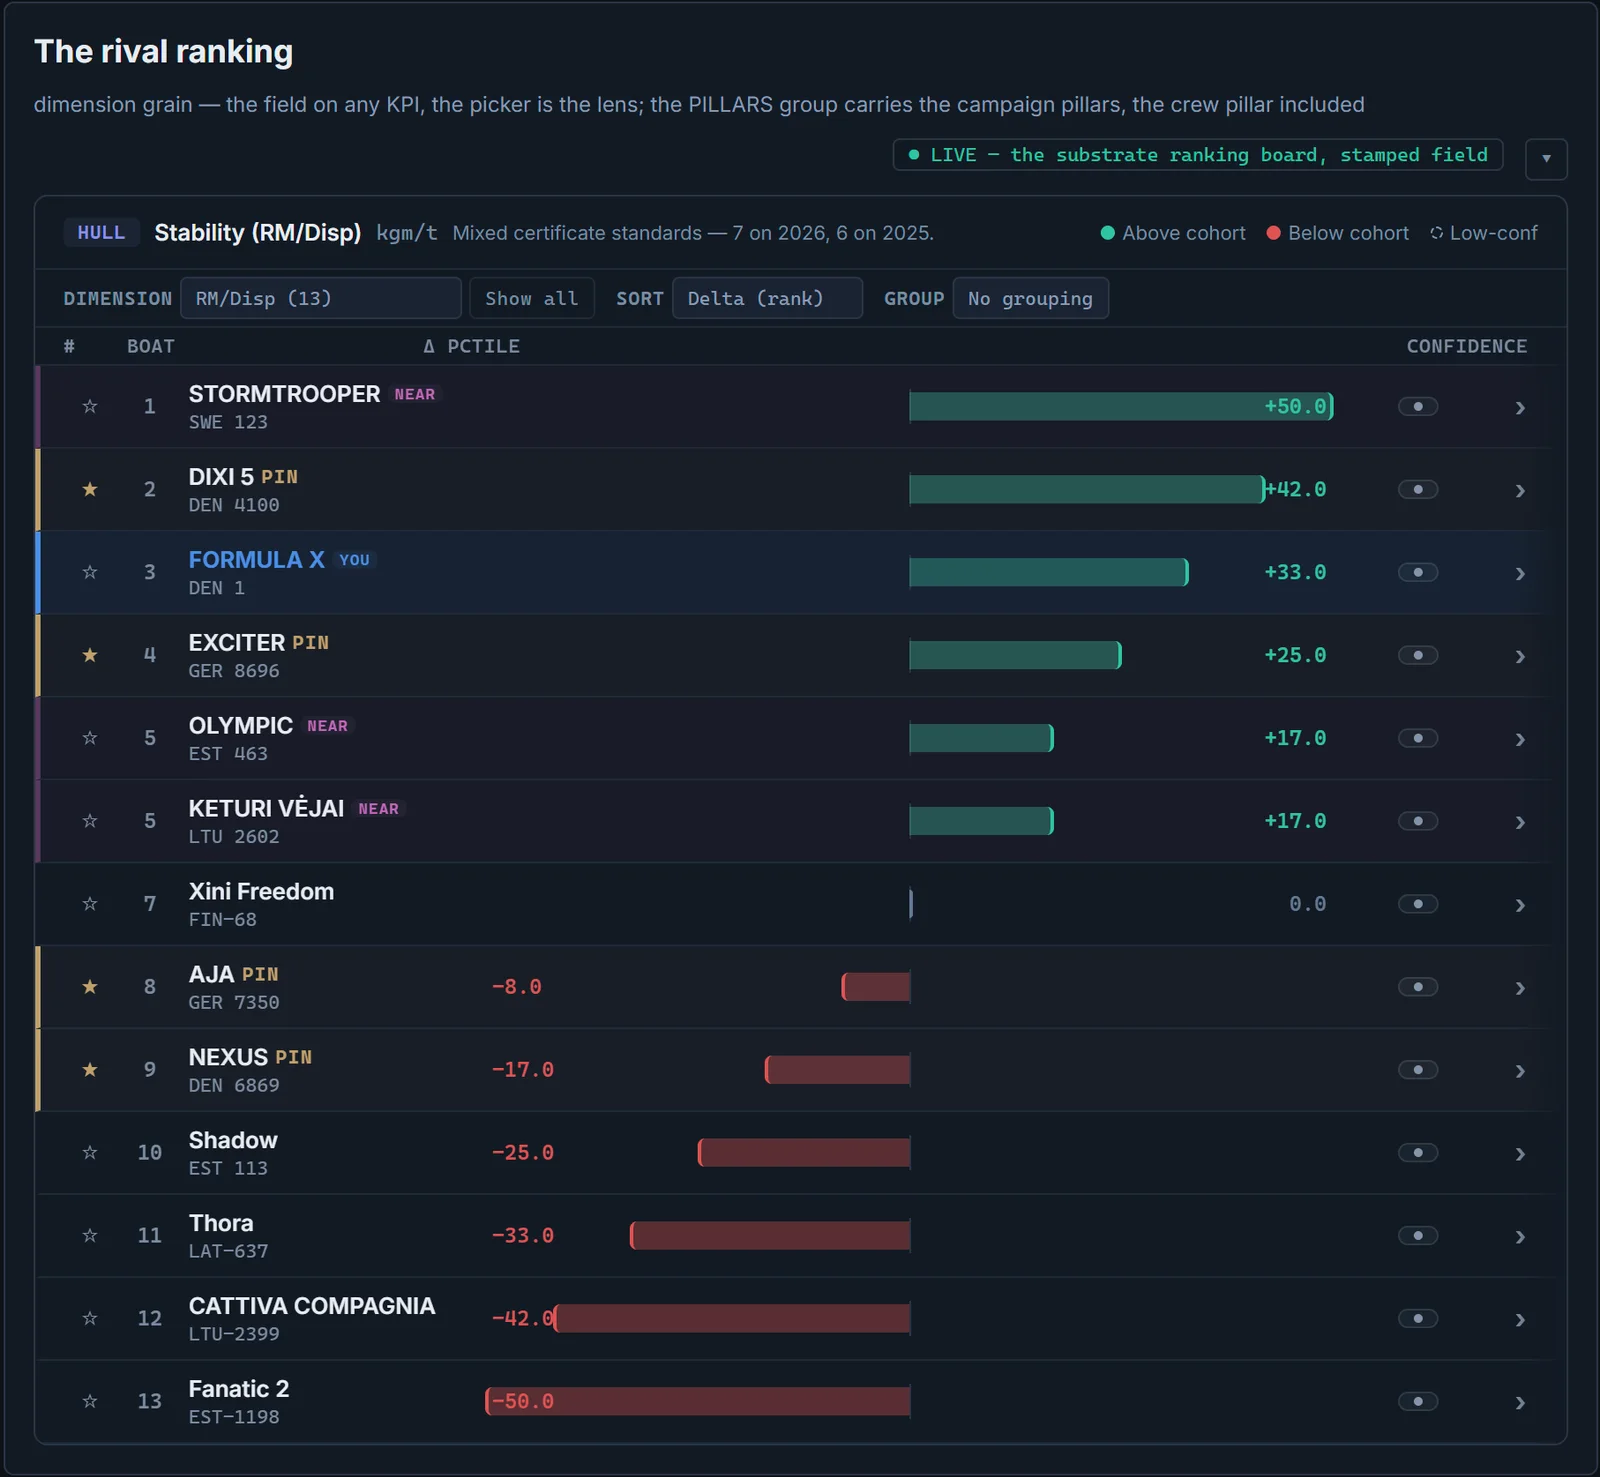
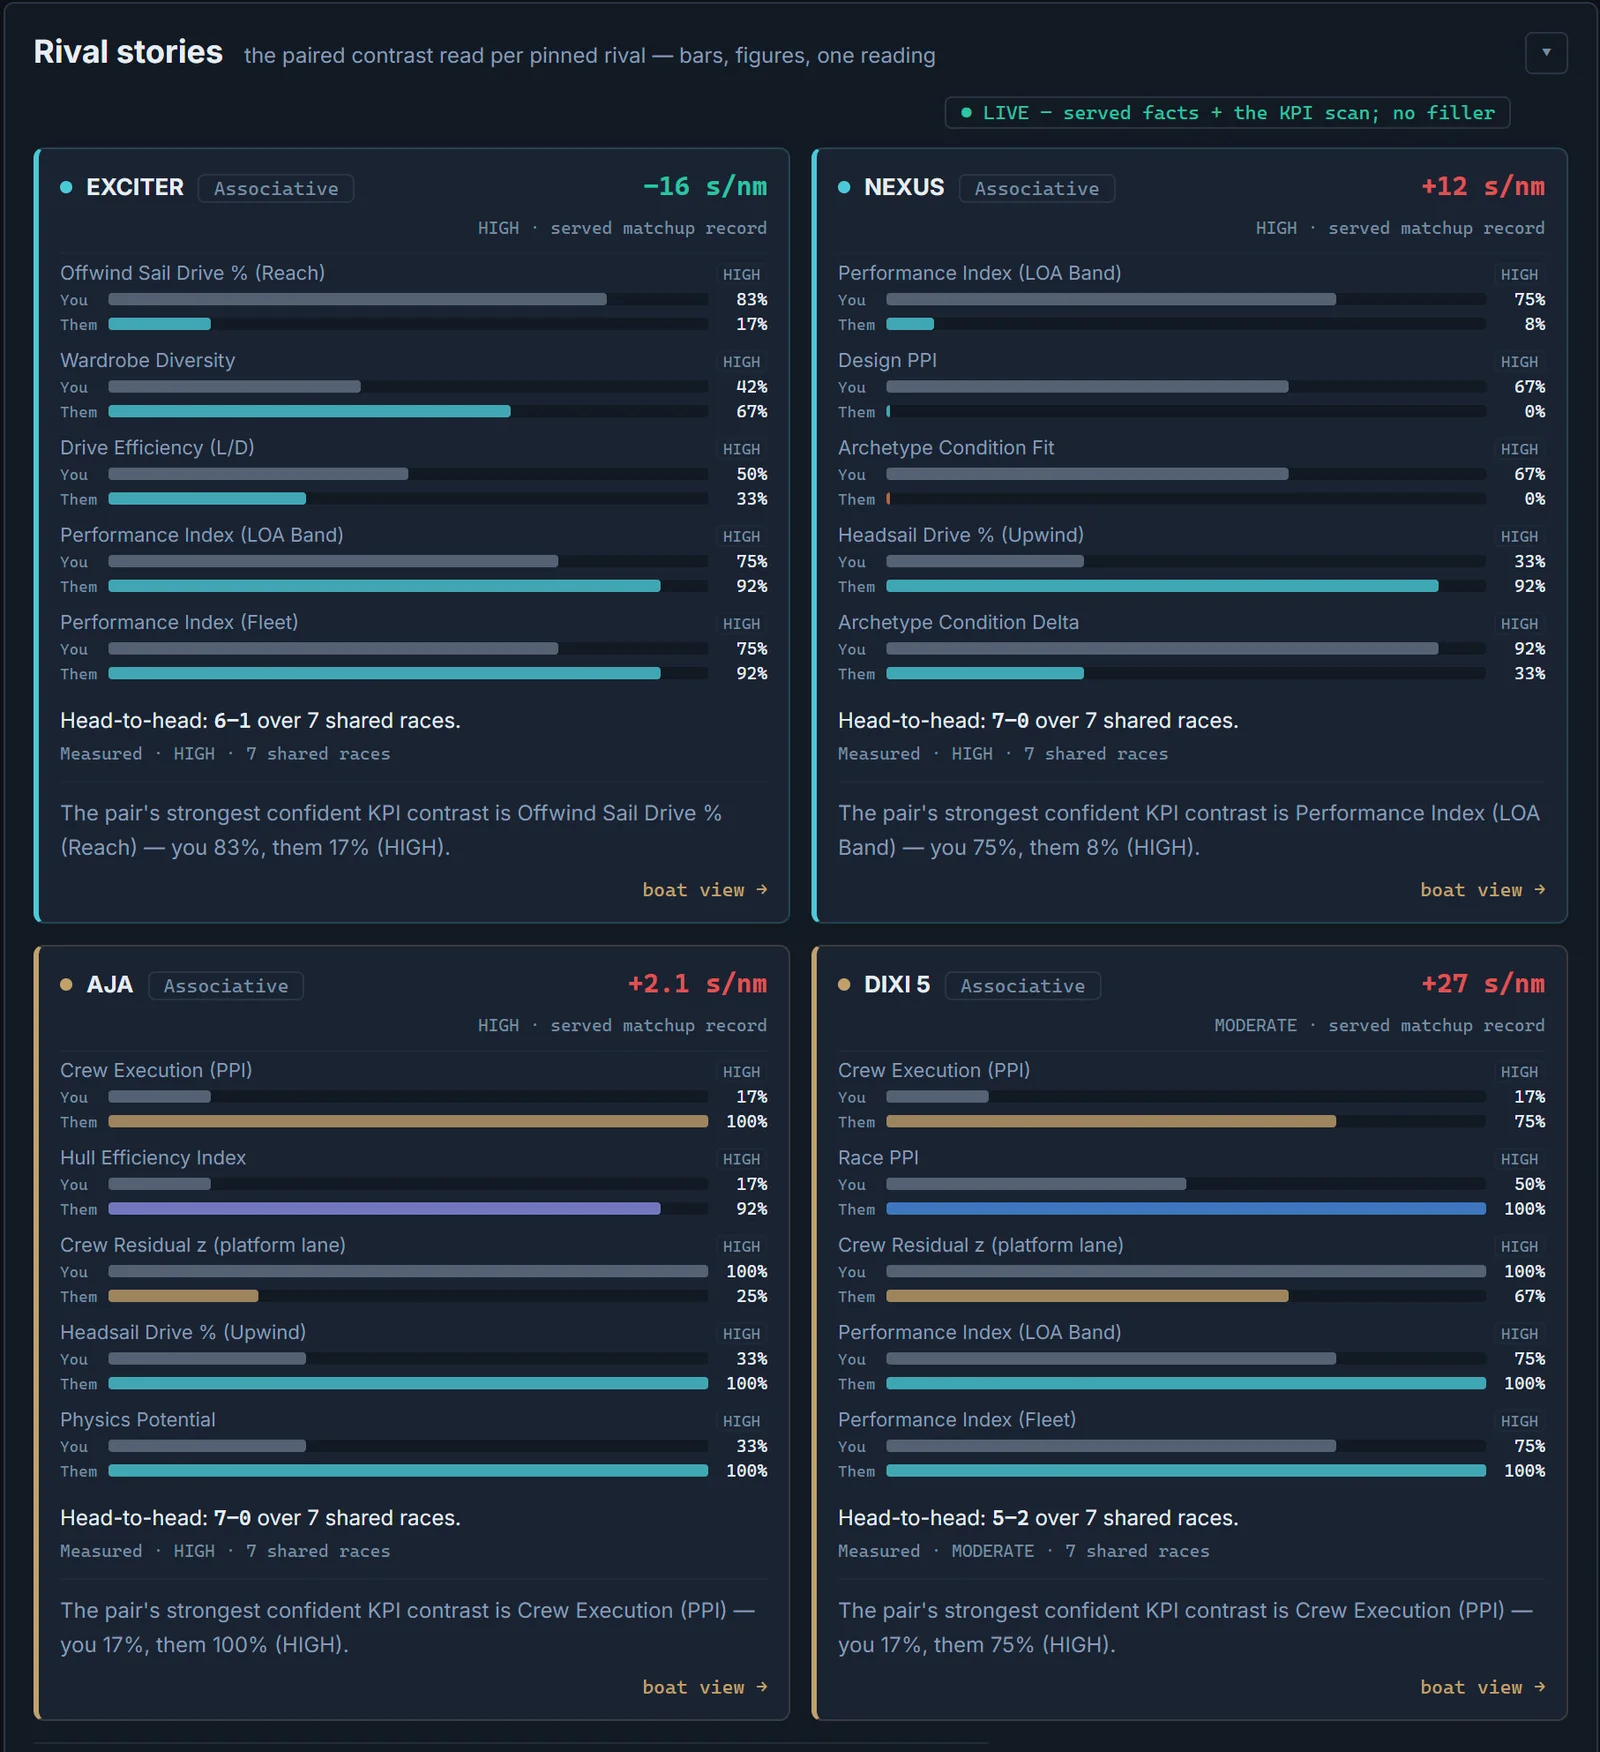
Preparation against a declared race.
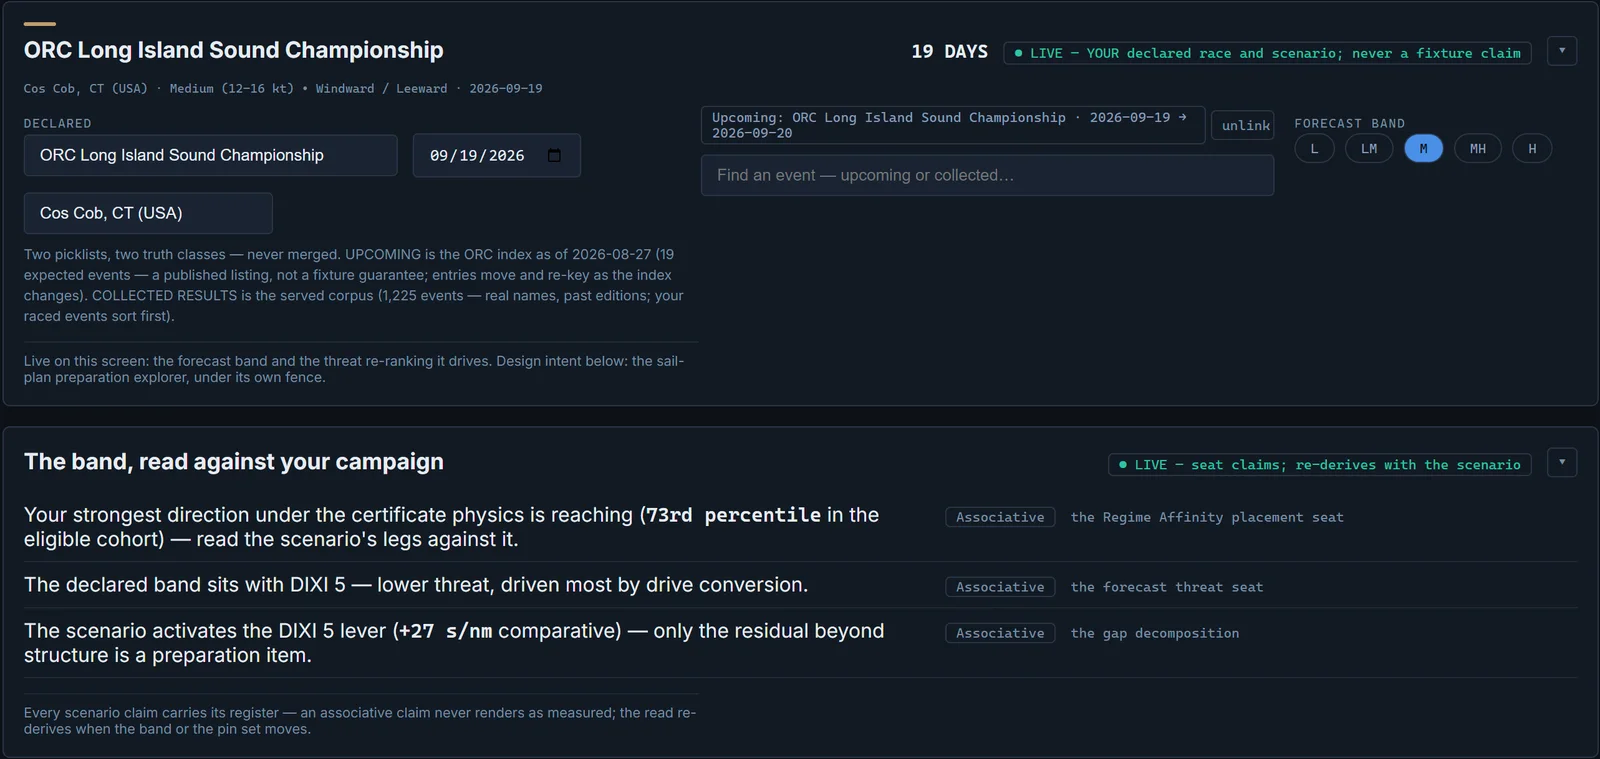
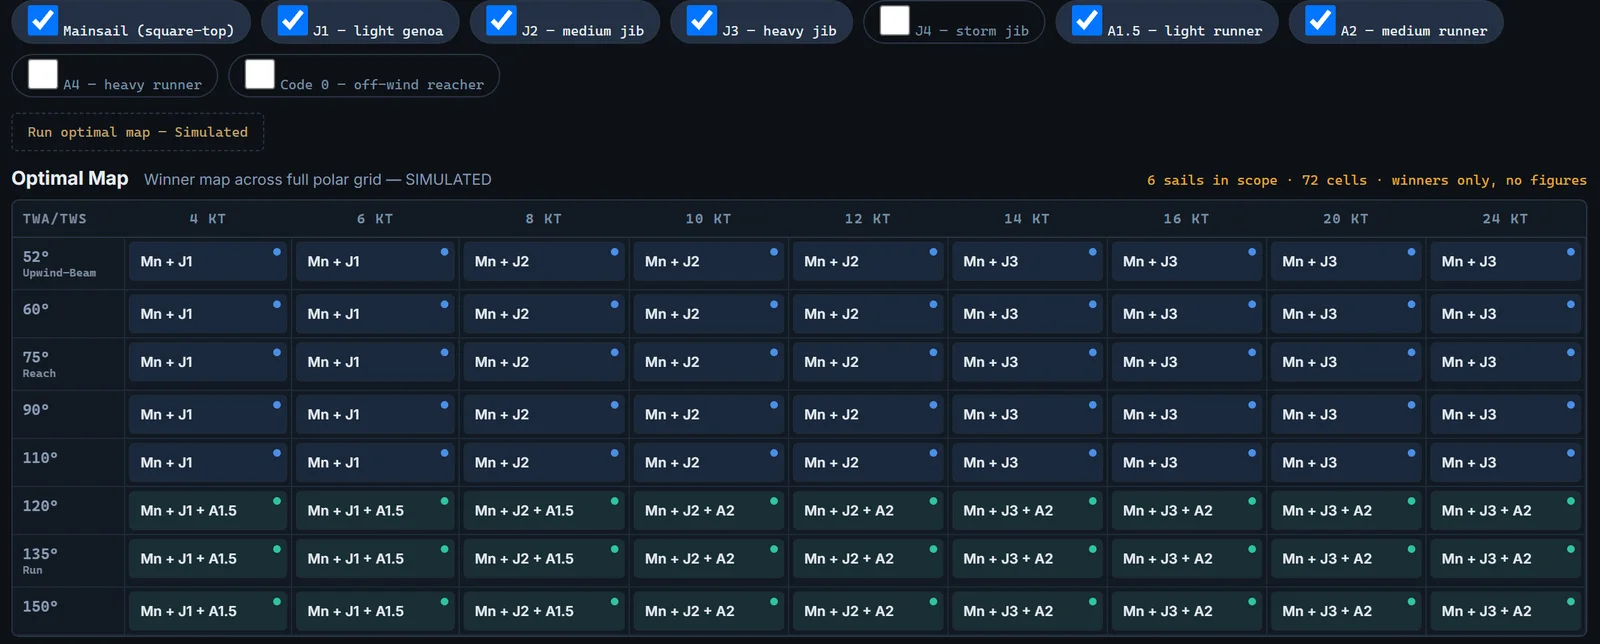
Declare the race, and the countdown, the forecast band and the claims about your boat line up against it — every claim carries its evidence label, and a claim based on association is never shown as a measurement. The sail-plan crossover explorer runs a simulated optimal map over a specimen wardrobe; the live flow will load your certificate’s declared inventory, and the panel’s own status label says exactly what is and is not claimed.
The pack the product prepares.
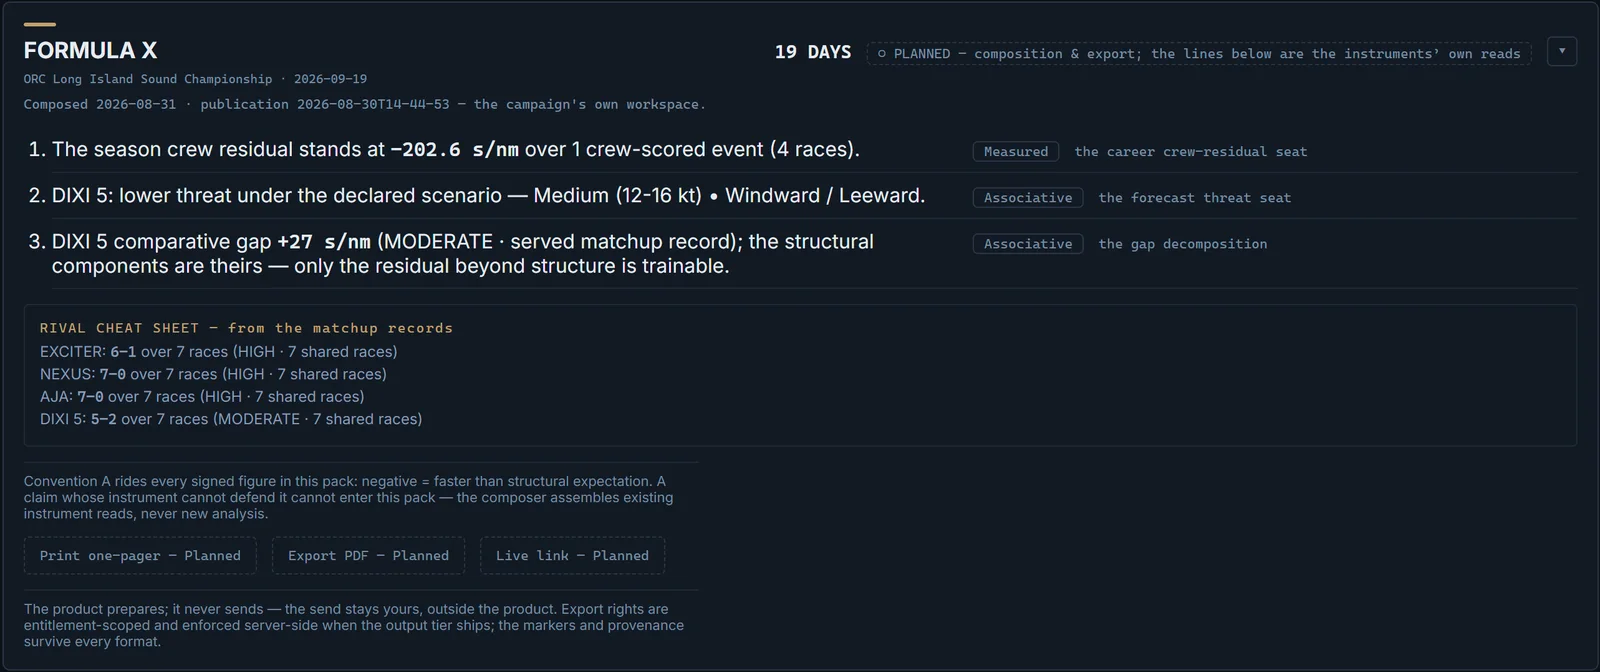
The briefing assembles only what the evidence supports — every line carries its evidence label and names the analysis behind it, and the rival cheat sheet composes from the matchup records. Export is deliberately marked Planned: the product prepares; the send stays yours.
Team Diagnostic, over the one App.
- PPI (the Performance Potential Index)
- crew pillar (the crew-execution share of PPI)
- condition fit (how well the design suited the conditions it met)
- crew-execution residual (a model-adjusted residual that helps investigate execution: what remains after the boat’s evaluated pace is accounted for — negative is faster, in s/nm)
Built on the FleetEdge platform, curated to a competitive team: your boat at full private depth, the rivals you meet across the season at comparison depth, and the crew pillar you actually control front and center.
Competitor × event map
Pin the boats you race and see PPI for every one, event after event — where you lead, where you trail, and against whom.
Three-pillar decomposition
Physics potential (the PPI pillar that captures hull and sail-plan efficiency, from the certificate alone), condition fit, and the crew-execution residual — confidence-tiered, with a reason chain. The private depth is on your own boat.
Stack-rank & compare
Sort the field by overall PPI or by the crew pillar alone, per event or per season — gaps in the boat and gaps in execution, read side by side.
Prepare for the next event
Set the expected conditions and a target rival, then explore sail-plan crossovers across the wind range. Directional guidance to plan against.
Wind-regime affinity
Where your boat’s edge lives across the wind regimes (a governed band of wind conditions — upwind, reaching or downwind — a race observation is assigned to) — and how that overlaps with the venues you race.
Your season on the record
Headlines, story cards, and the boat detail for every event you sailed — the published record your private read sits on.
The panels above run on FleetEdge analyses at the product’s own stated status — LIVE, UNDER VALIDATION, or PLANNED, declared on each screen: Boat detail Crew PPI · three pillars Dimension stack ranking Competitor context Wind-regime affinity Archetypes × conditions Fleet scatter Headlines Story cards
Deliberately not here: a rival’s private workspace — competitors appear at comparison depth from the same published results anyone can see, and you never see their what-ifs. Not one event — bound-to-one-event is Event Pack’s lane; this view crosses your season. No on-board telemetry: the residual is derived under the FleetEdge physics model, and a sail plan is directional guidance until you sail it.
Pin. Map. Rank. Decompose. Plan.
For campaign leads and coaches racing a season-long circuit against a known set of rivals, who want the one thing the scoreboard can’t tell them: where does the gap actually live, and how much of it is ours to move?
- Pin — open the team workspace and pin the boats you race across the circuit: your standing cohort (the boats a figure is computed over — a real entry list, a class, a fleet — named on every figure).
- Map — read the competitor-by-event grid: PPI for every rival at every event, where they lead and where they trail.
- Rank — stack-rank the field by PPI, then by the crew pillar alone, to see whose edge reads in the boat and whose in execution.
- Decompose — split your result and a rival’s into physics, fit, and crew — and see which pillar the gap reads in.
- Plan — pick the next event’s expected conditions and a target rival; get a directional sail plan for the band where your edge pays.
One design, four crews.
Three sister-ships took 1st, 2nd, and 4th in Class B at the 2025 ORC Worlds. A fourth — same hull, same rig, nearly the same rating — finished deep in the fleet. When the boat is held constant, what separates the winners?
This story is built from published race results. Your own diagnostic stays private to your team.
Tallinn, Class B — the natural experiment
Four Xr-41s inside a 12-boat comparison group (the product’s event cohort runs wider): the same 12.7-meter racer, four different crews, ratings within a handful of seconds per nautical mile. FleetEdge reads the whole cohort through one lens — what the design gave, and what remains to explain in how each boat was sailed.
The crew residuals line up with the finishing order
In the Study of this cohort (fleet view as of 1 July 2026), the four boats with negative crew residuals — FORMULA X, MABELLE II, DIXI 5, EXCITER — are exactly the top four finishers. FORMULA X’s −25.4 s/nm (seconds per nautical mile — pace normalized by distance) crew residual against DIXI 5’s −10.0 is the widest margin in that column — a reading to investigate, not a verdict.
FORMULA X — the win, read against her sister-ships
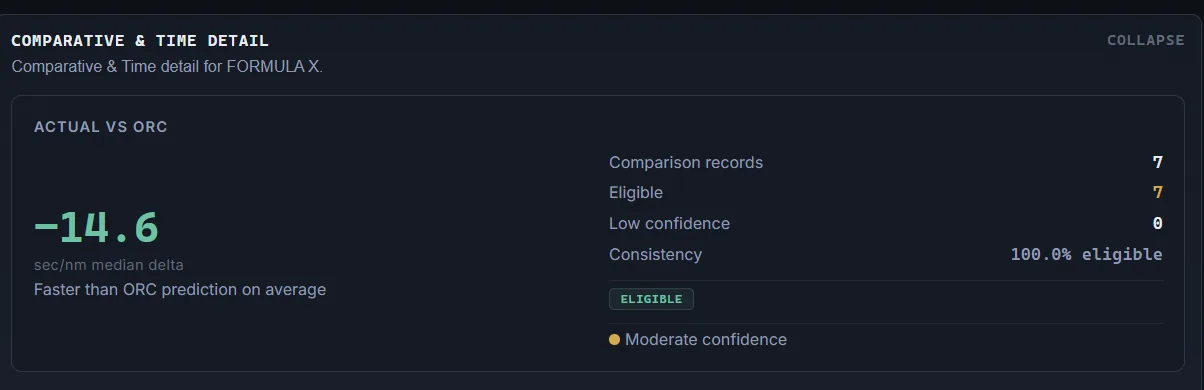
The platform gave her nothing her sister-ships didn’t have: near-identical certificate ratings across the cluster. In the Study, the win sits beside the best crew residual in the cohort — −25.4 s/nm — and the best race delta (−14.6): consistent with how she was sailed, and a model reading rather than proof of it. The boat view carried the diagnostic behind that reading; the current publication serves this event’s crew column differently, so no current frame can reproduce the Study’s read — the figures here are the Study’s, and the beta product itself now runs a live campaign on the same boat: the walkthrough above is her live campaign, on her most recent collected season.
The decomposition, behind the readout
The crew-execution signal across the campaign’s eligible records — stated as bounded, not causal, with that line in frame.
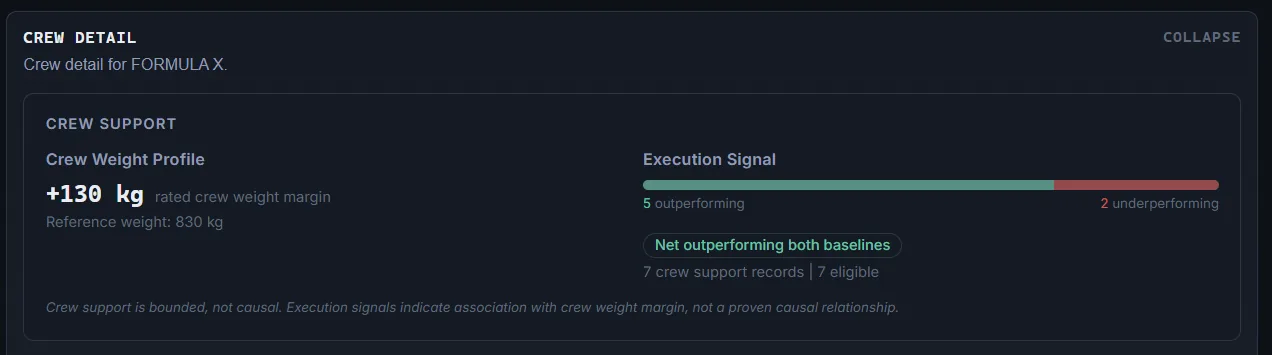
The decomposition methodology is under on-site validation — readouts are directional and say so.
XBOX — same platform, deep in the fleet
The fourth Xr-41 is the comparison boat: same hull, same rig family, a near-identical certificate rating — and a +37.1 s/nm crew residual in the Study that left her deep in the fleet. Across four near-identical platforms the finishing spread follows the crew-residual column more closely than the certificate. A sistership comparison reads what happened; it is not a controlled test: sail inventory, preparation and the conditions each boat met can differ, and they remain possible explanations. The +37.1 (positive = pace given away) is the versioned Study’s figure; the crew pillar the product reads today is on screen in the beta walkthrough above.
Race by race, the story holds
Seven eligible comparison records sit behind the winner’s median delta — the diagnostic isn’t one race’s verdict, it’s the series’ shape.
A note on the numbers above — figures come from different captures and are not interchangeable:
1. The Formula X/XBOX story cites the versioned FleetEdge Study (fleet view as of 1 July 2026), frozen with that artifact; the walkthrough screens show the beta product’s own live read, captured 30 August 2026 — a different statistic, on a different basis and a different publication, with no equivalence claimed at any grain.
2. Boat and event counts in the walkthrough reflect only that capture, not this site’s published macro figures.
3. The two legacy App frames in the story (captured 10 July 2026) keep their own as-of captions and may carry the prior rating scalar (the certificate’s reference rating figure) and a since-retired crew display in-frame; no figure on this page is quoted from either.
4. Crew analytics in the current product are execution-only.
5. The status labels — LIVE, UNDER VALIDATION, PLANNED — are the product’s own vocabulary, declared panel by panel; a panel’s label governs its claims, and nothing here claims an unshipped tier early.
6. Beta access is by request, and customer campaigns stay private to their teams; the walkthrough is our own demonstration campaign on published race results.
The diagnostic builds on the FleetEdge crew and physics layer — how it works: Team Diagnostics, Crew & Execution, and The Physics.
See it against your own work.
Team Diagnostic is in beta — access by request. Scope: one boat — yours. No other team, federation, or public surface can see your view.