Place a design against its peers.
FleetEdge Design Benchmarks · Beta
How does this design measure up against the boats it races?
You get: a dated study of the boats it met — who is in the comparison, what each certificate says, and how each boat raced against its rating.
Beta — access by request · The screen is the product’s own study on the public corpus; the office’s private tier is planned.
Which boats does your design really race, and how does it measure up against them? Pick the design and the classes it meets. Design Benchmarks builds a cohort (the boats a figure is computed over — a real entry list, a class, a fleet — named on every figure) from the ORC certificates and the published race record, and returns a dated study: who is in the cohort, what each certificate says, and how each boat has raced against its rating, with the limits of every claim marked.
How the study is built: the census first, the certificate as the ground, the race record read against the rating, every read composed by source, no verdict issued, and the claim boundary drawn.
For naval architects, sailmakers, and lofts. Private study of the published fleet; private certificate intake is planned. Access by request.
Method: Event Retrospection Story: Formula X against the classes she meets, at the 2025 Worlds The public corpus; the office’s private tier planned
The sample, the limits and the next step
See a sample: Formula X against seven boats she met at the 2025 Worlds, below.
The limits: the public corpus today — every ORC-certificated boat of the classes you pick; the office’s private tier is planned, and a certificate you upload today goes through the standard public-data submission process. No official result is claimed, and no design is called better without its conditions attached.
Next: request a benchmark sample, or beta access — the product opens once your access is granted.
Beta — access by request · The product is running: the screens below are the product’s own study on the public corpus, in beta. Every panel carries its own mark in the screen — ready or waiting, live or not yet available — and a panel’s mark governs its claims. The office’s private tier is planned, and the product says so on its own face.
One design, several types of study.
A design benchmark validates a design by a few methods, and the product names them in its own words. Its types of study (the product’s own word is “posture”): retrospective by default; prospective, which states a hypothesis before the read; and a design what-if, which evaluates a change. Behind the question compared to what? it offers five study designs: the design under study against a reference cohort built from the classes she meets; an event cohort — everyone who raced an event she raced; a design cohort — her certificate alone, no comparison; a race micro-cohort of her actual rivals under an event, which arrives with the event’s conditions and entry record; and a perturbation study — a governed what-if against fixed peers — which waits on the evaluation feature. A second journey, the Design Launch, serves a design launch or a campaign triage.
The walkthrough below runs the first type of study on the first design: Event Retrospection — the design under study against the classes she meets, read back from an event the cohort shared.
A loft’s question usually starts with the fleet.
Which boats does this design race, what do their certificates say, and how have they raced against their ratings? Design Benchmarks answers that from public ORC certificates and published results, for the classes you pick.
When the question becomes one boat or one sail-plan change, SailEdge™ by SailrScience is the workbench for it.
Event Retrospection: Formula X at the 2025 Worlds.
The subject is Formula X, an Xr-41. The comparison is seven boats she met, picked from the classes she meets — X-41, X-41 Mod, Italia 11.98, Farr 40 OD — read back from the Garmin ORC World Championships 2025 (the site’s published event page). The question, from the product’s own frame: where does Formula X give time away against the classes she meets? Nine chapters follow the product’s own rail; the figures stay in the screens.
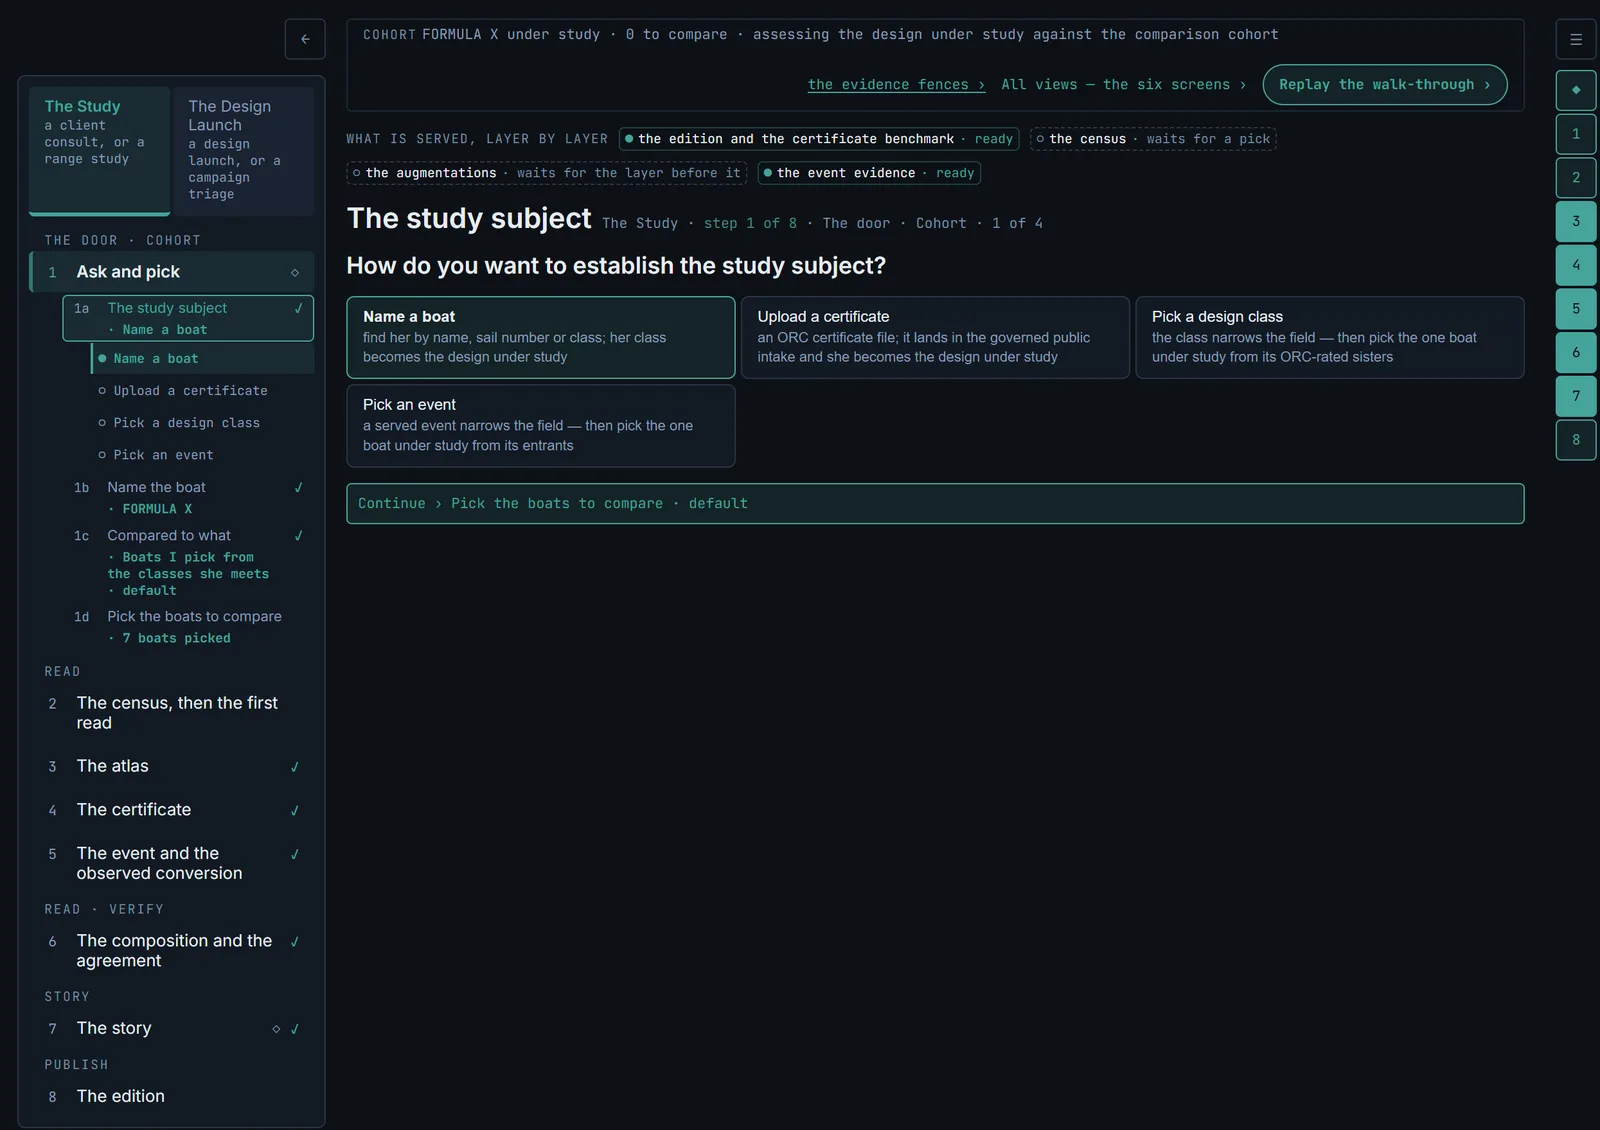
Ask and pick.
The door names the subject and proposes the comparison — the classes she has raced against, pre-picked from her record and edited by hand — and sets the type of study: retrospective, at boat grain. Every line on the rail is a door, never a control; the study so far sits beside the work and each step ticks as it is answered.
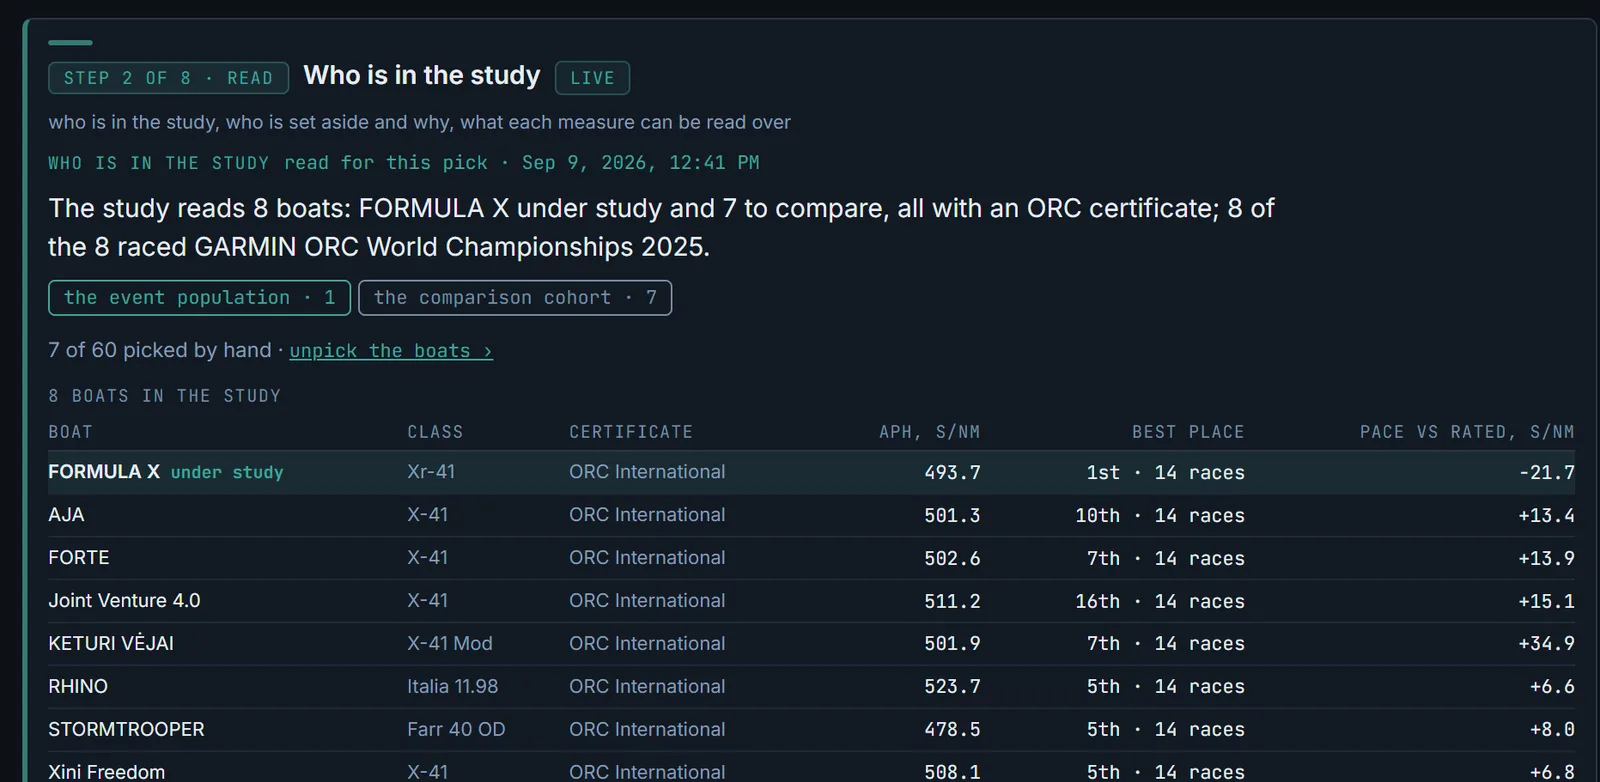
Who is in the study.
Eight boats, every one holding an ORC certificate, every one an entrant at the Worlds. On the FleetEdge comparison ranking she placed first among them over her races and sailed faster than her rated pace at the event; each comparison boat sailed slower than its own. The census reads before any map — who is in, who is set aside and why, what each measure can be read over.
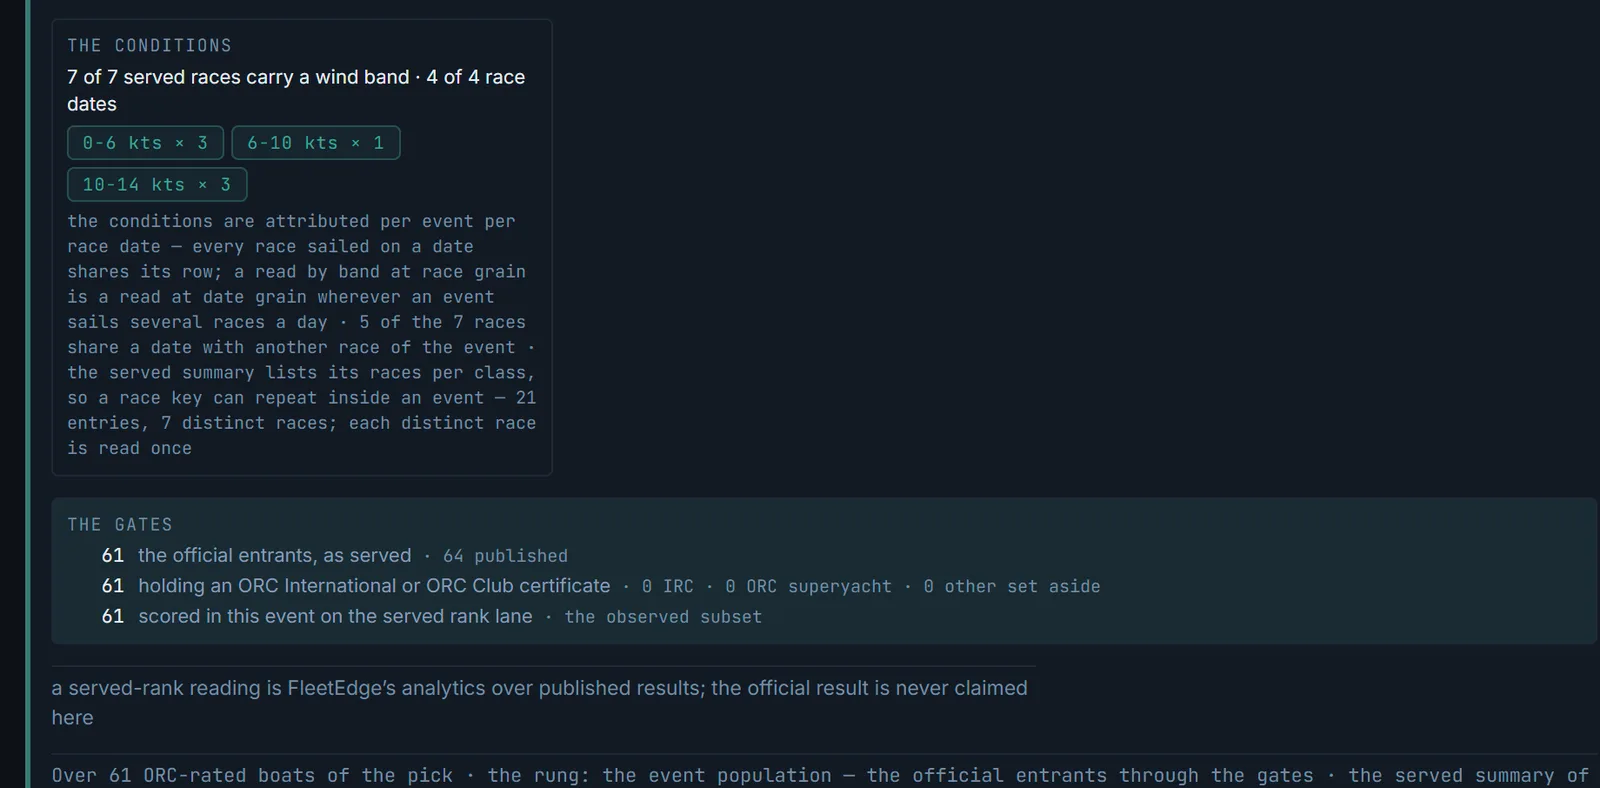
The event’s conditions and entry record.
The record (the product’s screen calls it “the event contract”) is in place before any observed read: seven races over four race dates, the wind band on every race — light to moderate air — and the gates: the official entrants as published, all certificated, all scored on the FleetEdge comparison ranking. Beneath it the product’s own line: a served-rank reading is FleetEdge’s analytics over published results; the official result is never claimed here.
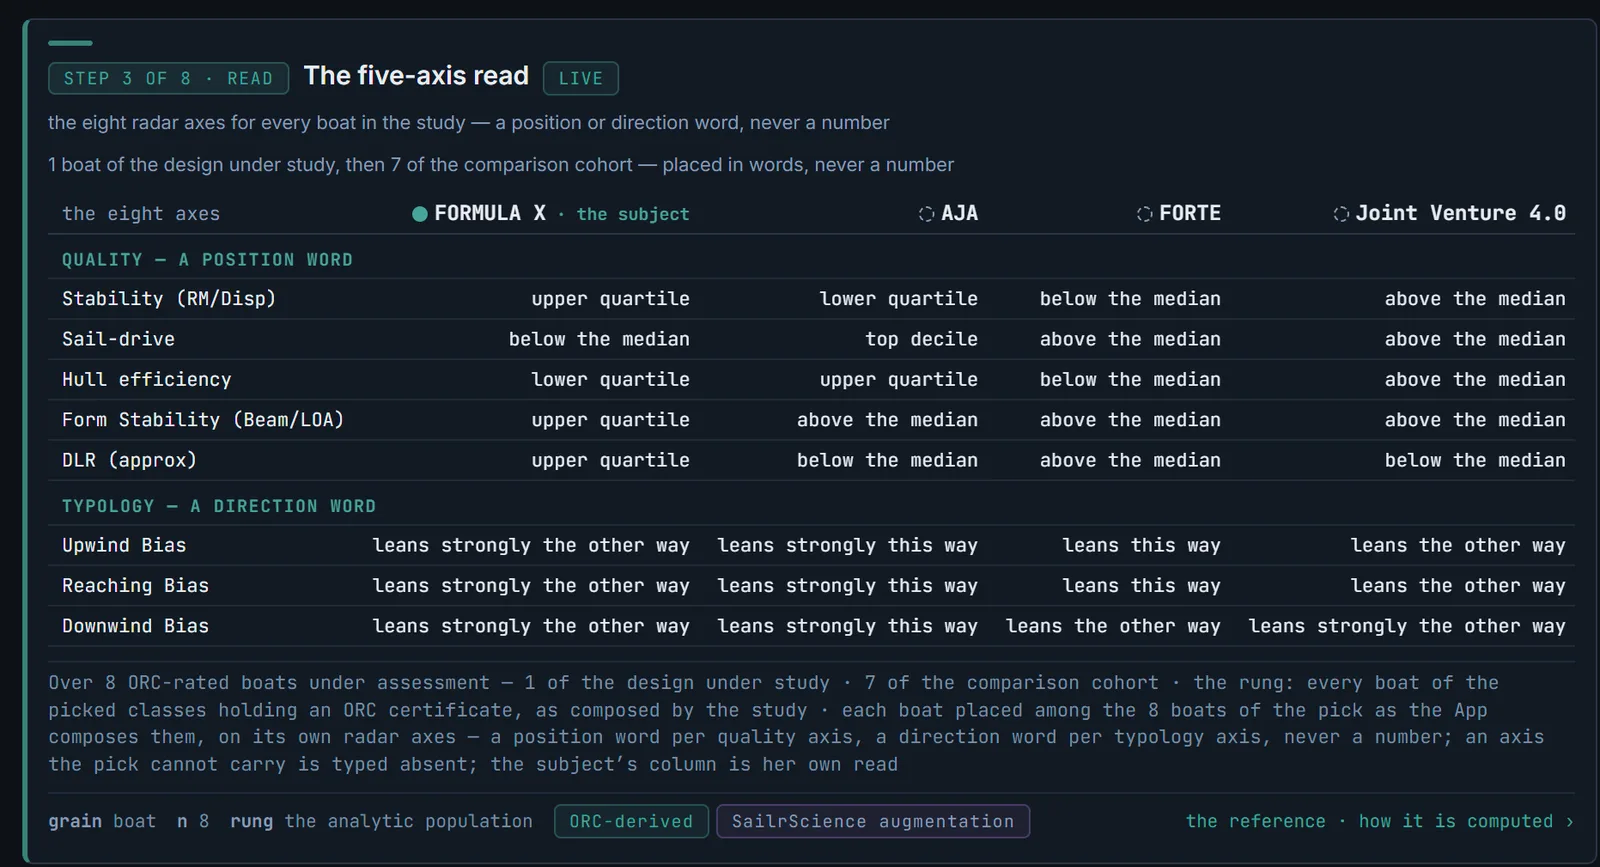
The atlas.
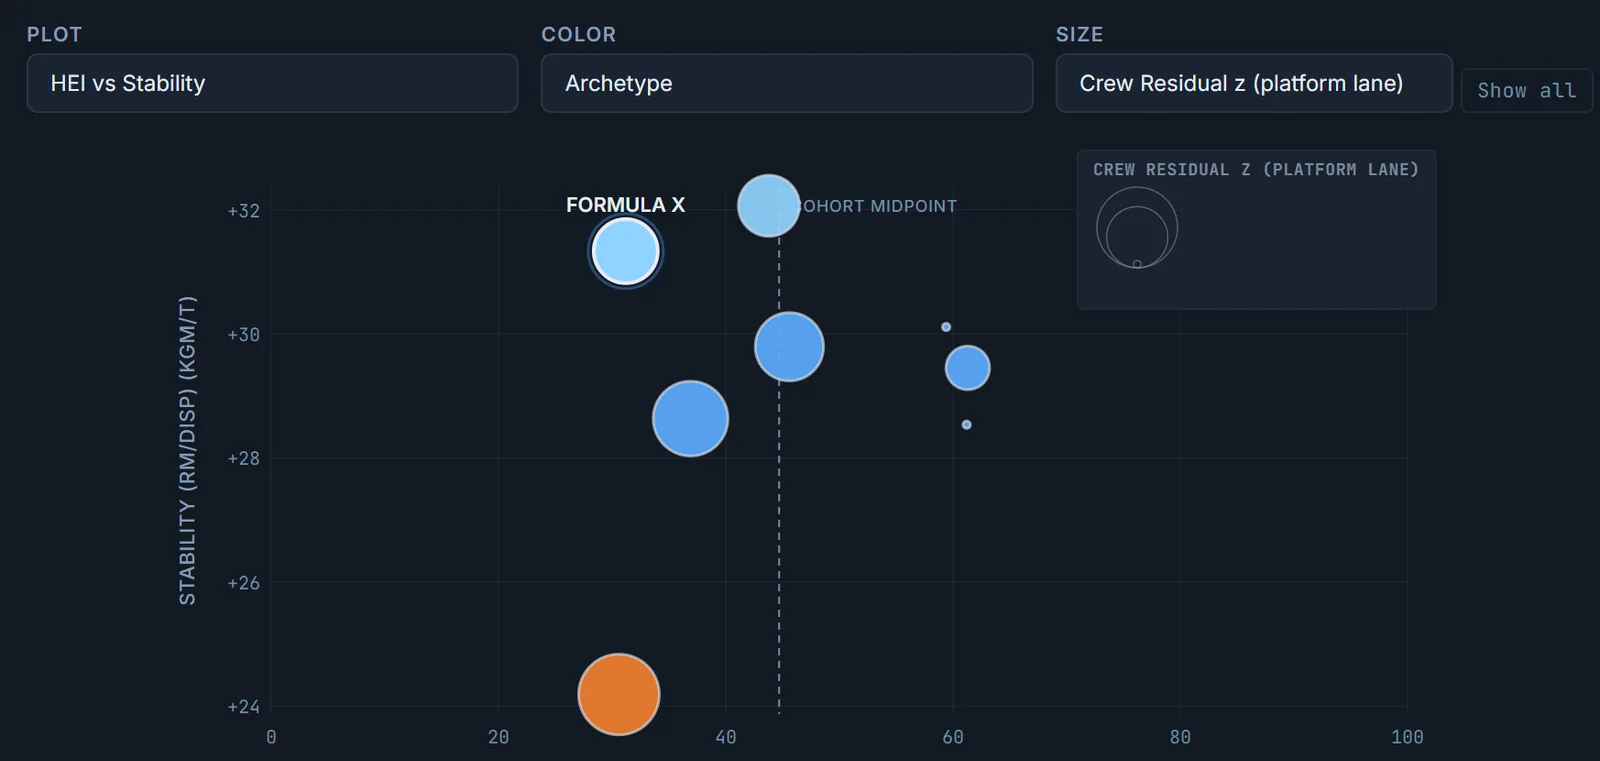
The five-axis read places every boat in words, never a number. Formula X reads upper quartile on stability (how much righting moment the boat carries relative to its displacement), on beam to length and on displacement to length; below the median on Sail Drive (the sail-drive force, in newtons, at the 12 kt upwind baseline from the certificate’s ORC VPP); lower quartile on HEI (the Hull Efficiency Index — a drag-derived read of hull form, ranked against its cohort); and leaning strongly the other way on every bias — a powered, stable platform with a less slippery hull. The X-41 sisters read the other way round.
The structural scatter draws the triangle — drag efficiency against righting moment — with the design under study marked at its stable, less-slippery corner and the cohort midpoint drawn. The stack rank and the archetype (one of the fleet’s eight recurring design types) list complete the atlas: one dimension at a time against the comparison’s median, and the eight grouped by the registry’s words as a representation, never a performance order.
The certificate.
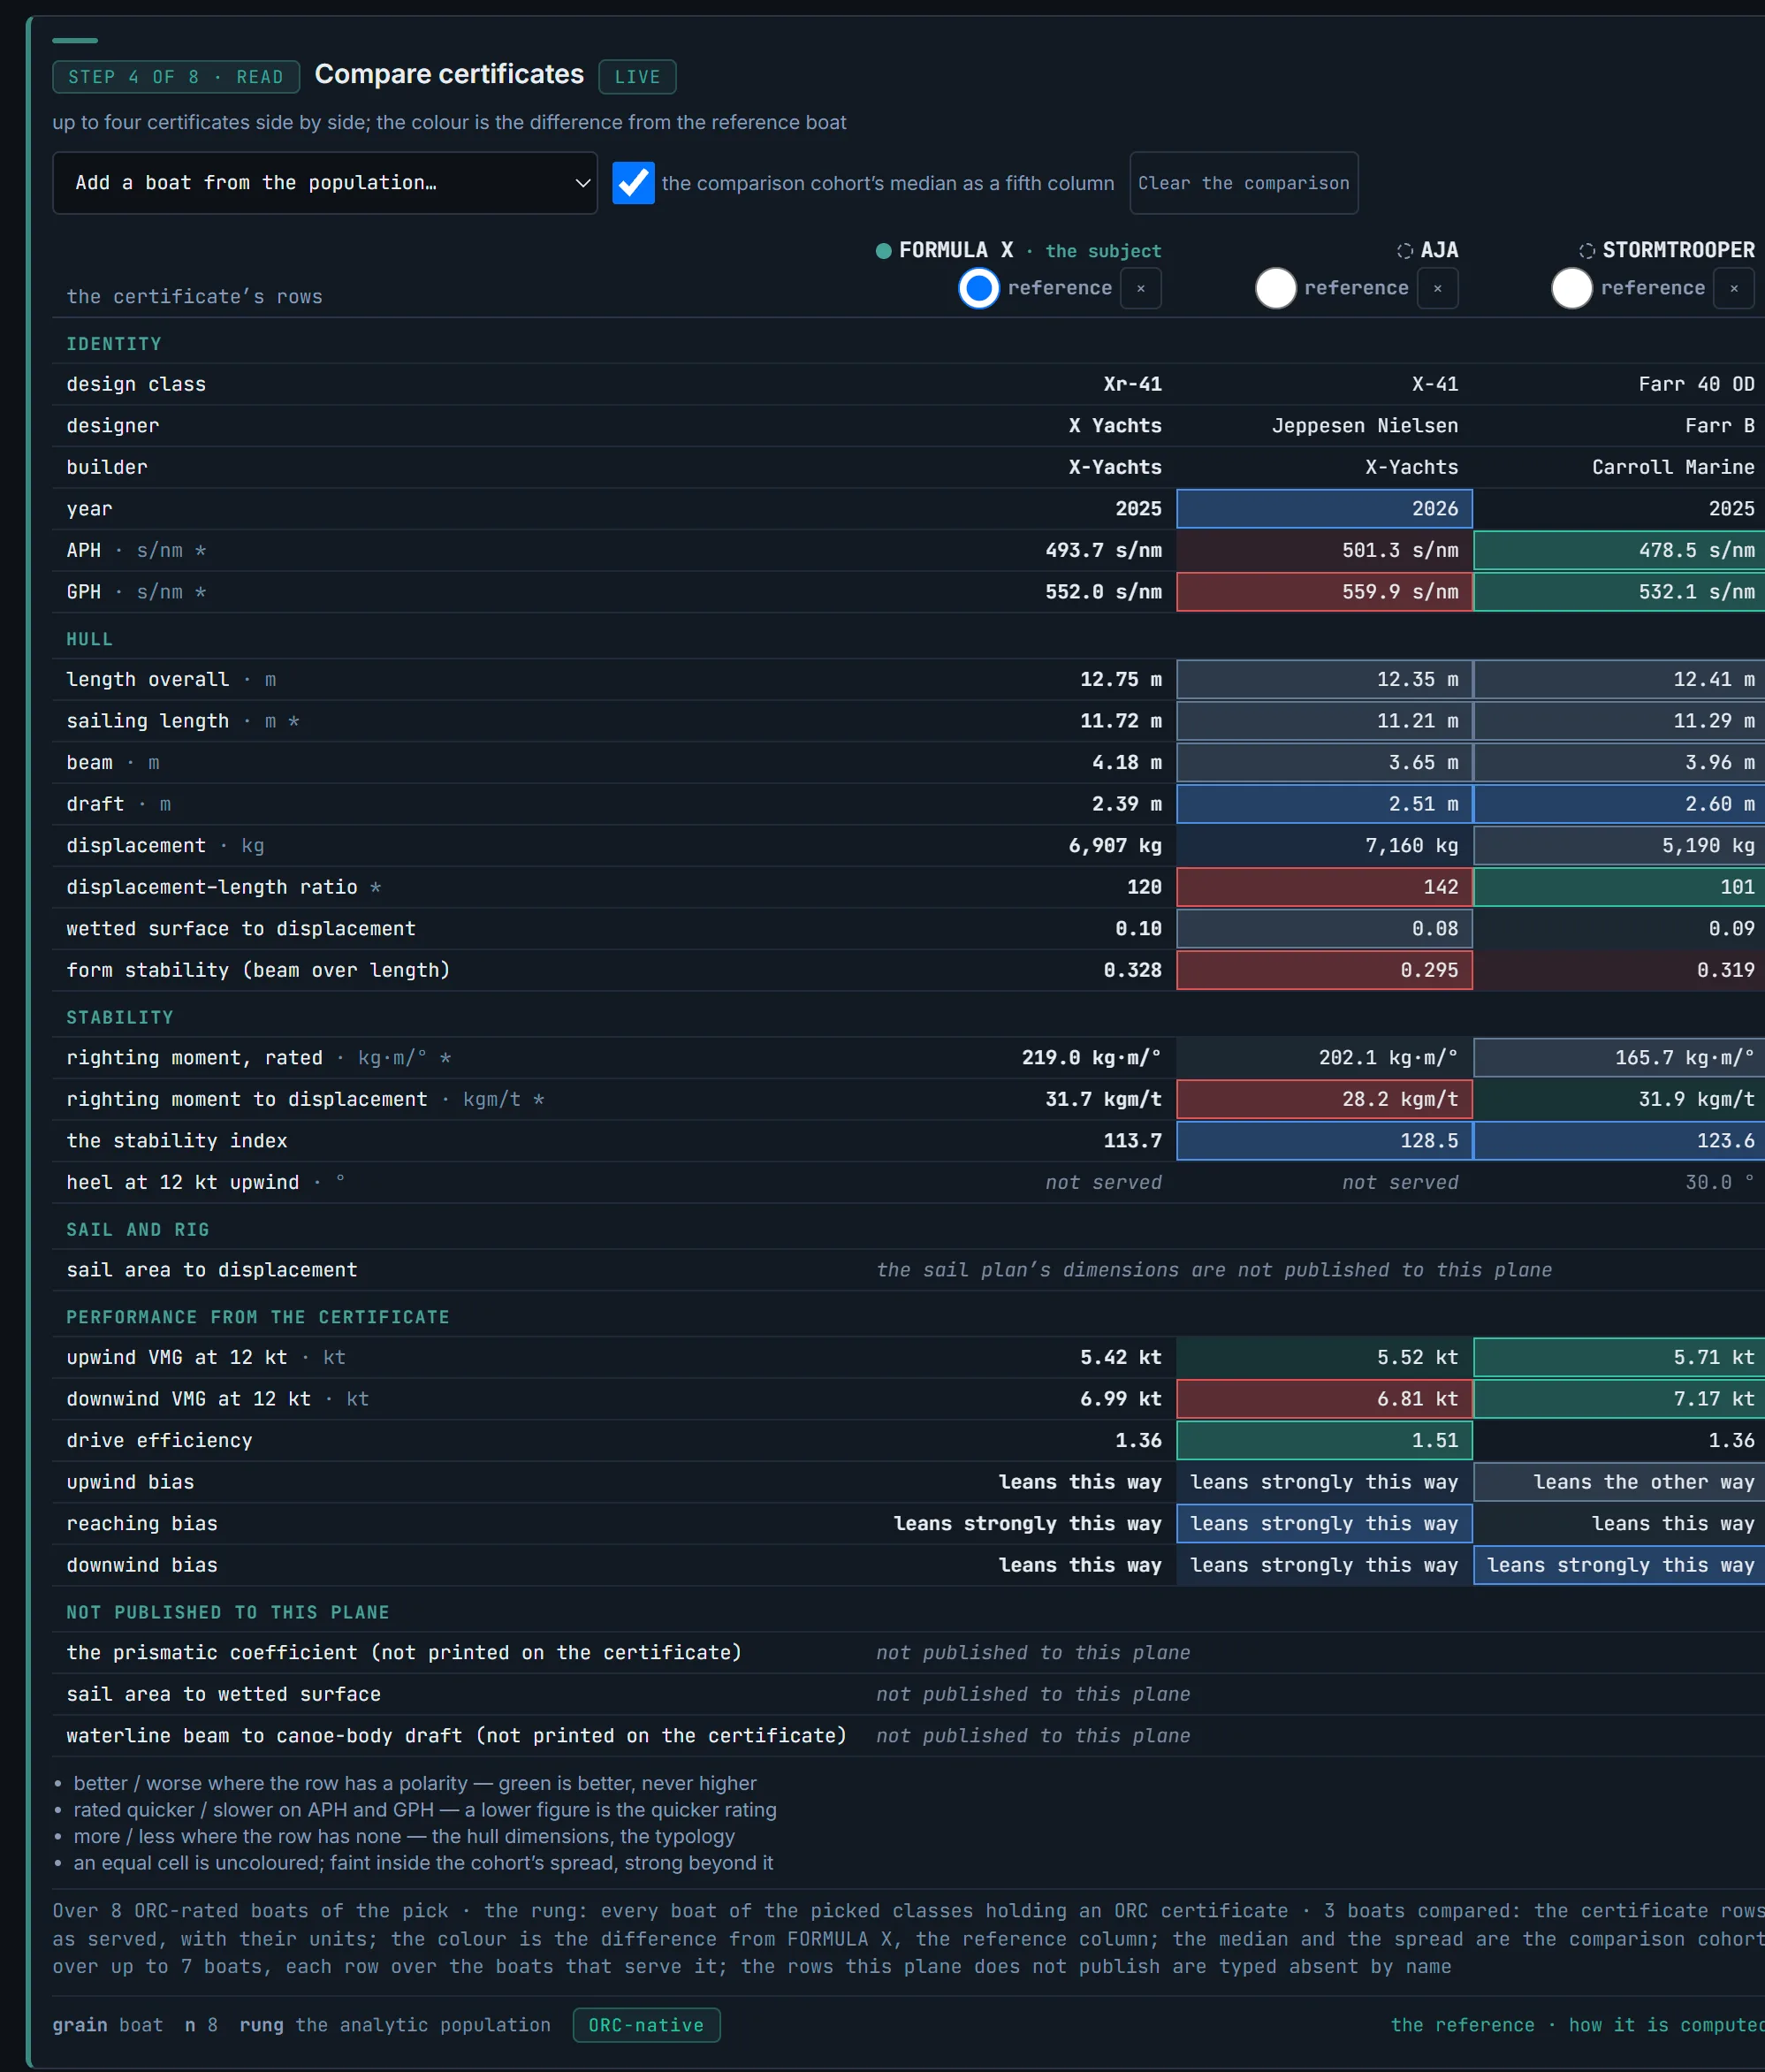
Up to four certificates side by side, the color on every row the difference from the reference boat: identity, hull, stability, performance from the certificate — and the rows this plane does not publish, each marked as not published by name.
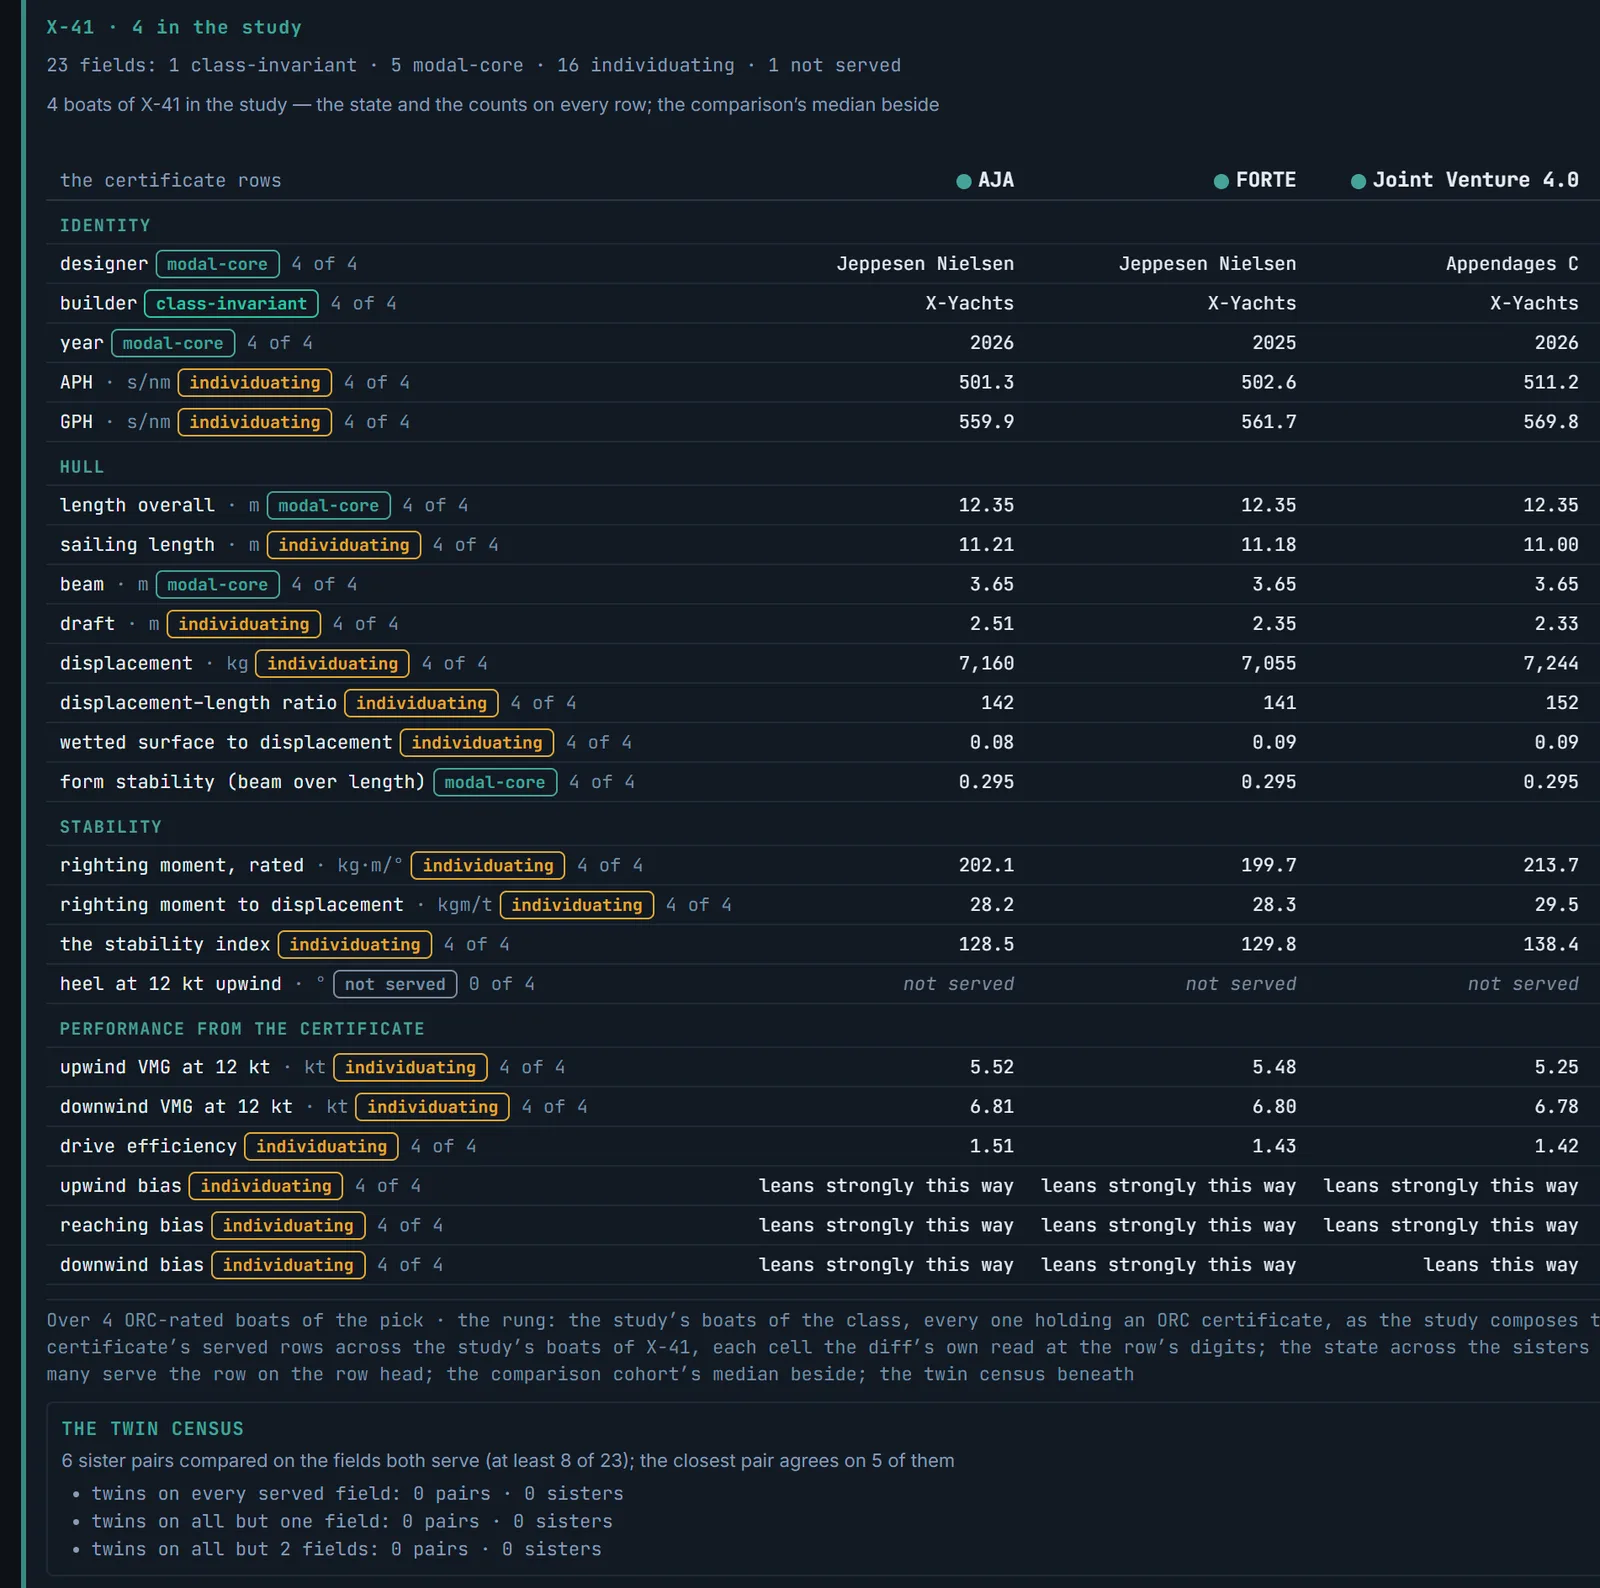
The variance ledger reads a class’s sisters across every published row and tags each — class-invariant, modal-core, individuating. The four X-41 sisters agree on five of twenty-three fields, and the twin census finds no twins. A class is a name; a boat is a certificate.
The event and the observed conversion.
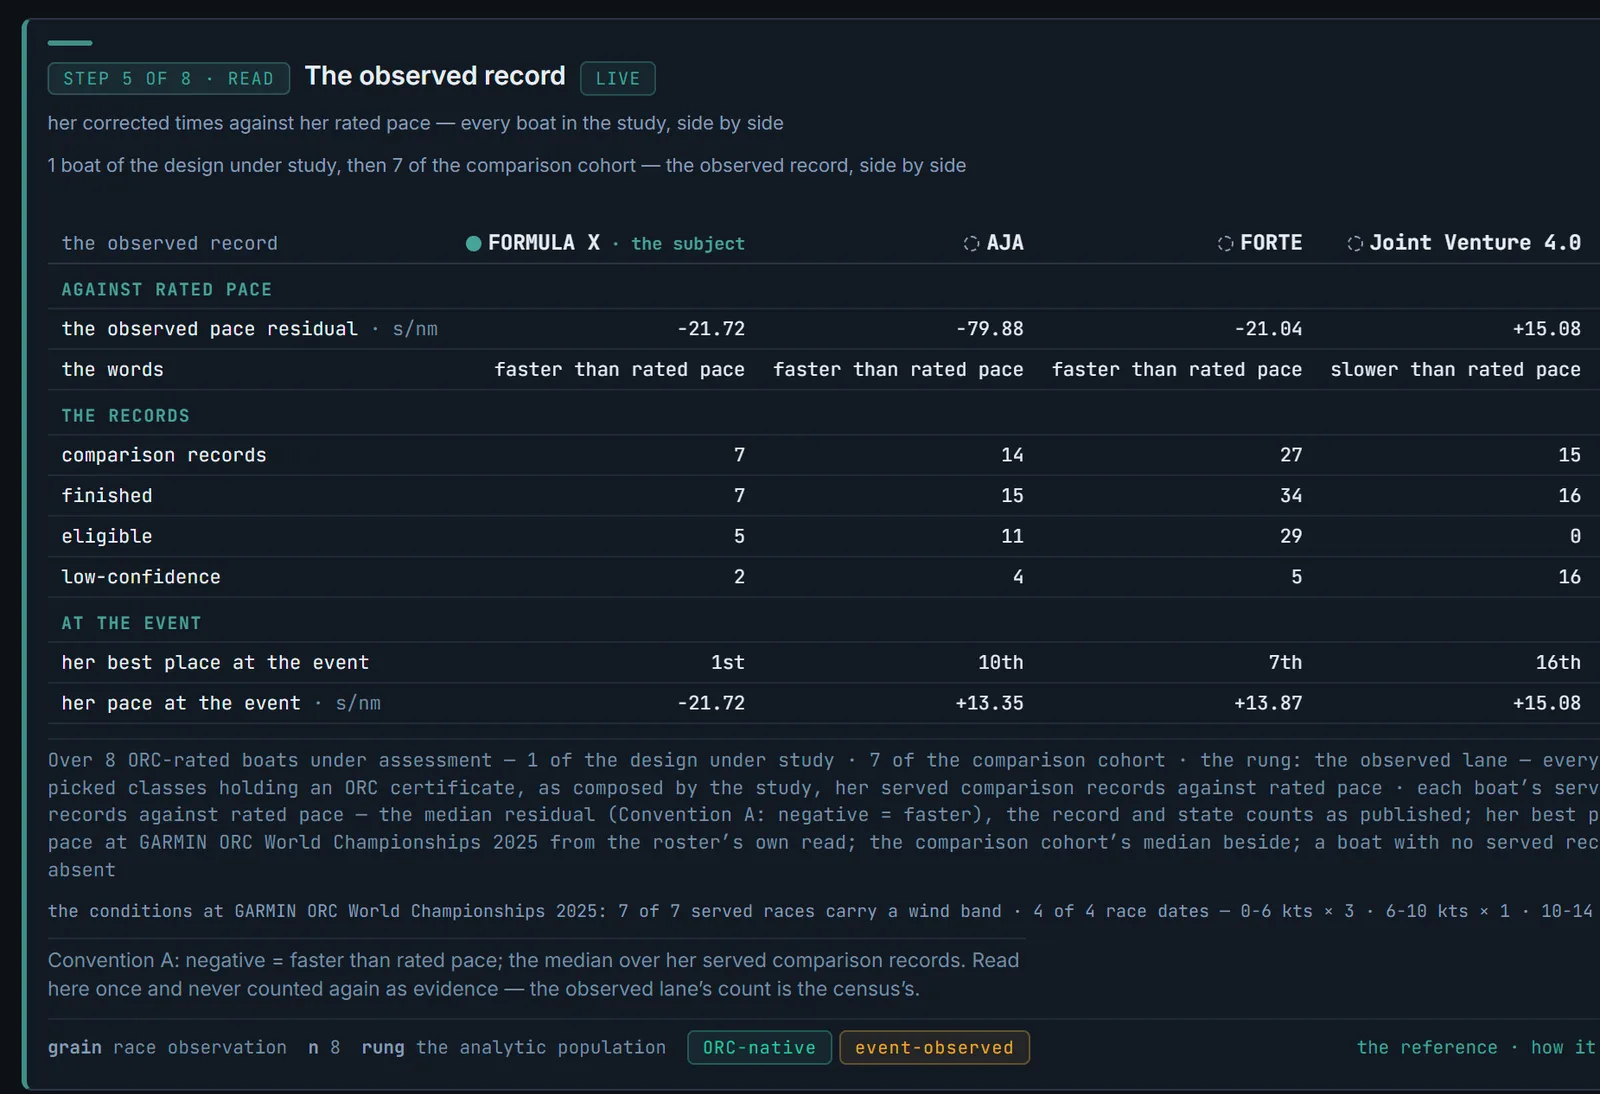
Her corrected times against her rated pace, every boat side by side: faster than rated at the event and over her published records alike. The sister that runs fastest over her season sailed slower than rated at this Worlds. The records and their confidence sit beside every read; a boat with no published record is marked absent.
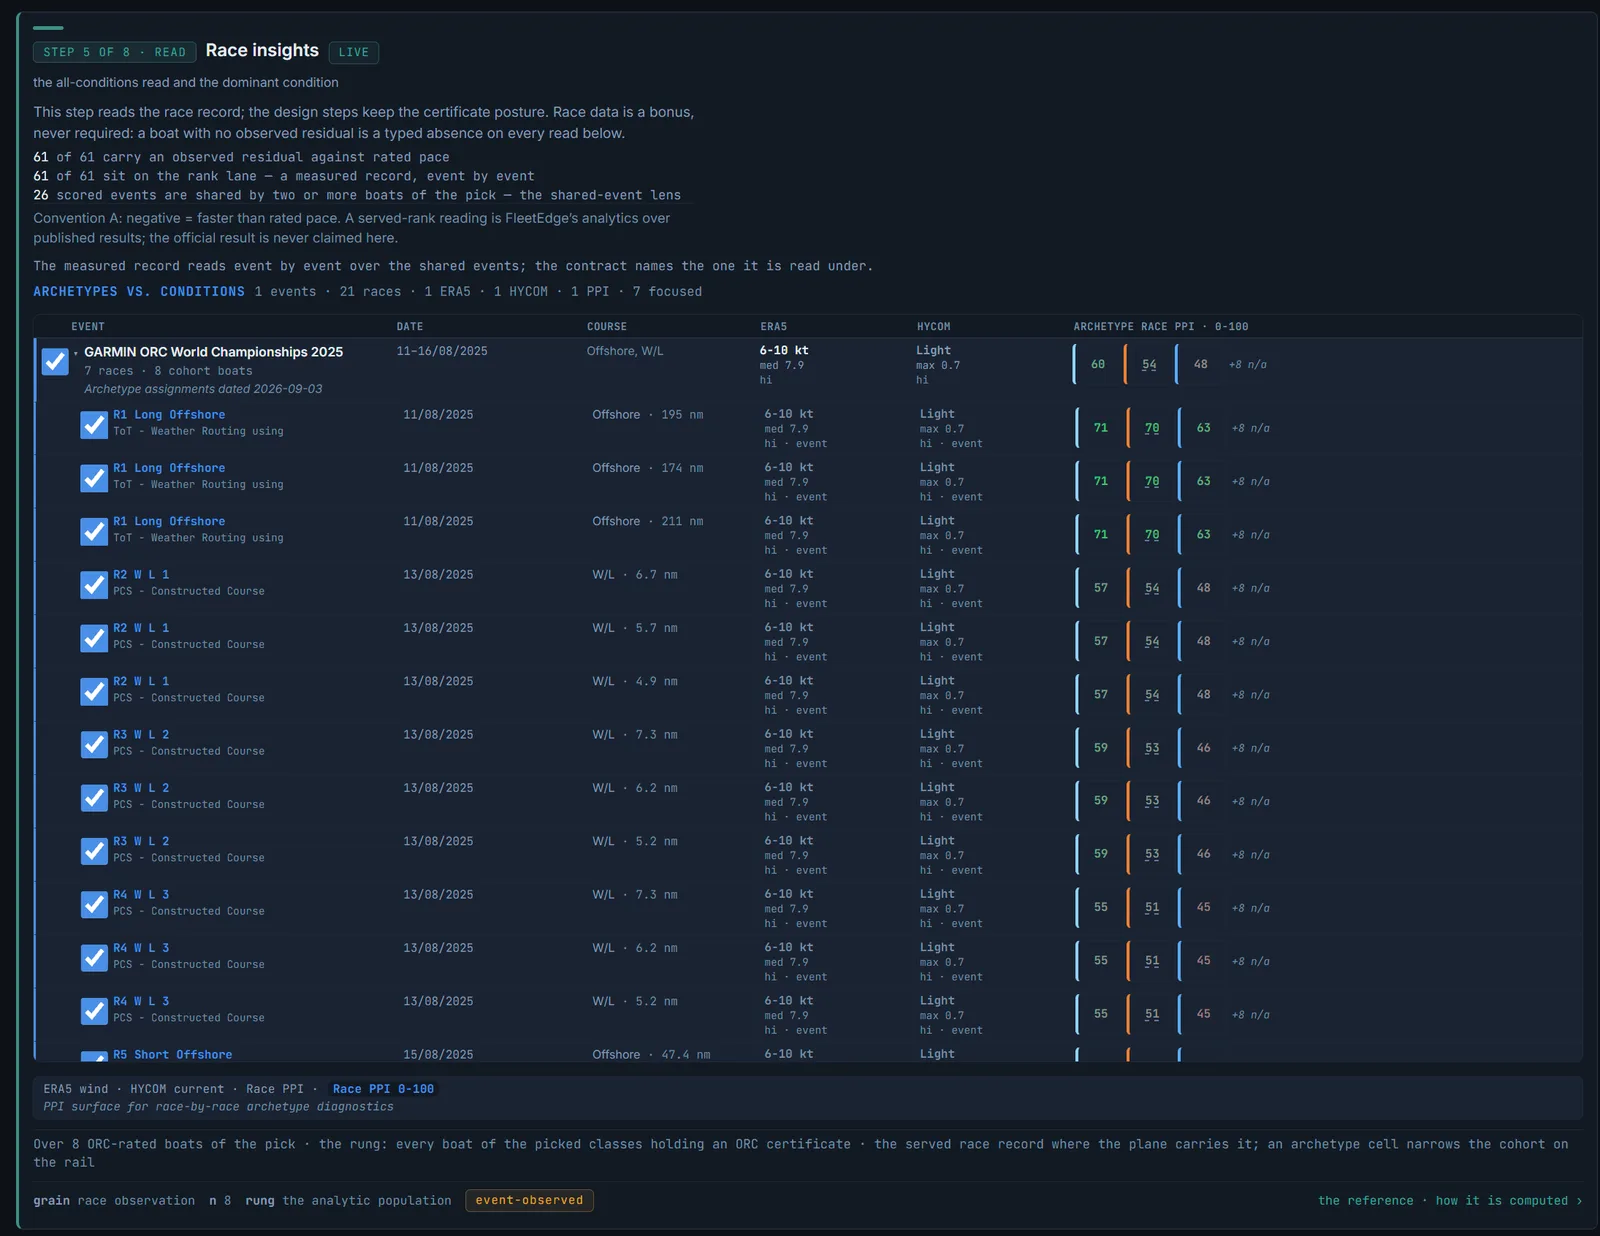
Race insights lay the Worlds out race by race — each race’s course, wind and current beside the archetype read — the all-conditions read and the dominant condition. Race data is a bonus, never required: a boat with no observed record is a typed absence on every read.
The composition and the agreement.
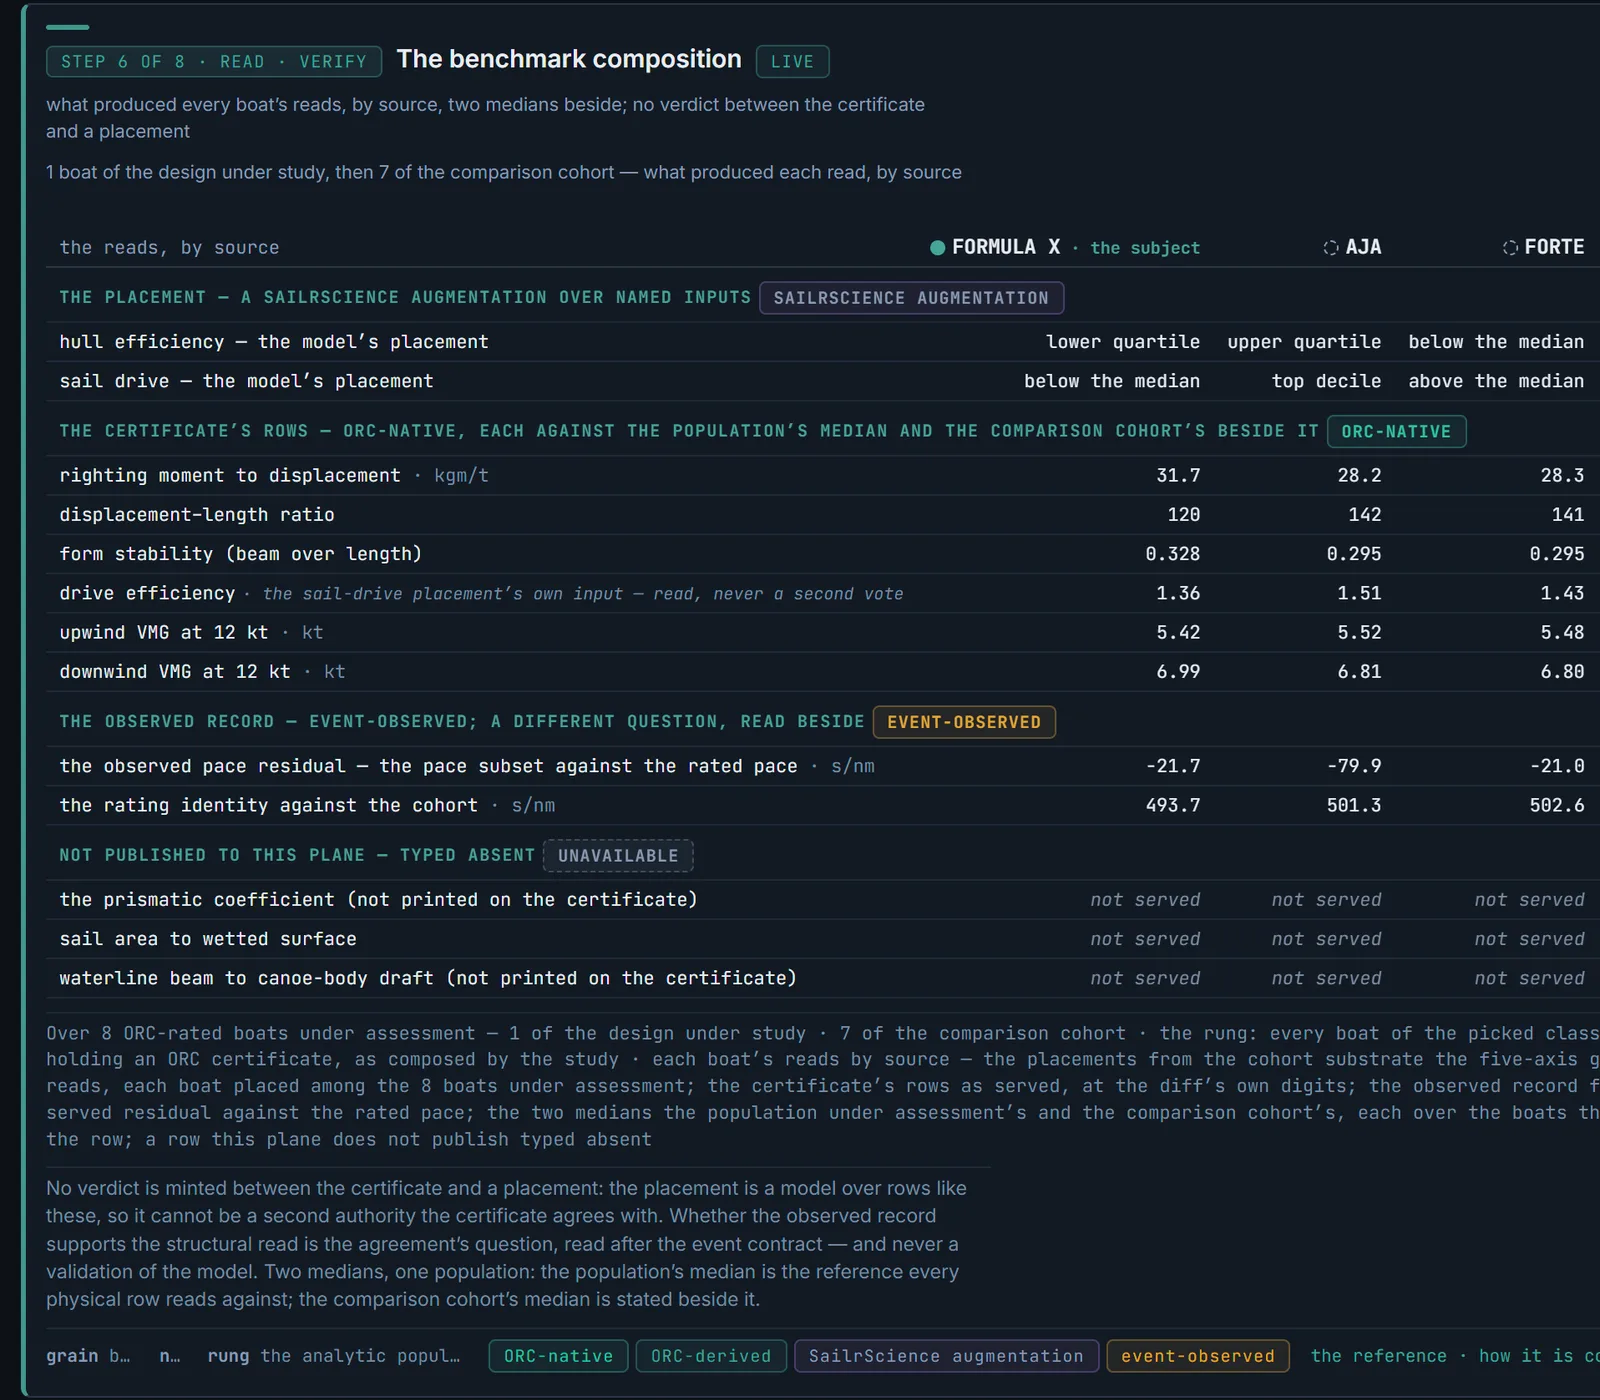
What produced each read, by source: the placement, an augmentation over named inputs; the certificate’s rows, ORC-native; the observed record, event-observed; the rows not published, marked as such. Two medians, one population. No verdict is given between the certificate and a placement; whether the observed record supports the structural read is the agreement’s question, read after the event’s conditions and entry record, and never a validation of the model.
The story.
The mismatch shortlist is hypothesis-grade, never a score: where a class’s structural position and its record disagree. The X-41 reads structurally weak and competitively strong; the Xr-41 upper quartile and faster than rated. Then what this benchmark can claim — the cohort’s membership under the rule, the refusals and their counts, the archetype cross-section as a representation — and cannot: any ordering of the archetype words by performance; any official result; anything about an office’s private boats; a what-if as a measurement.
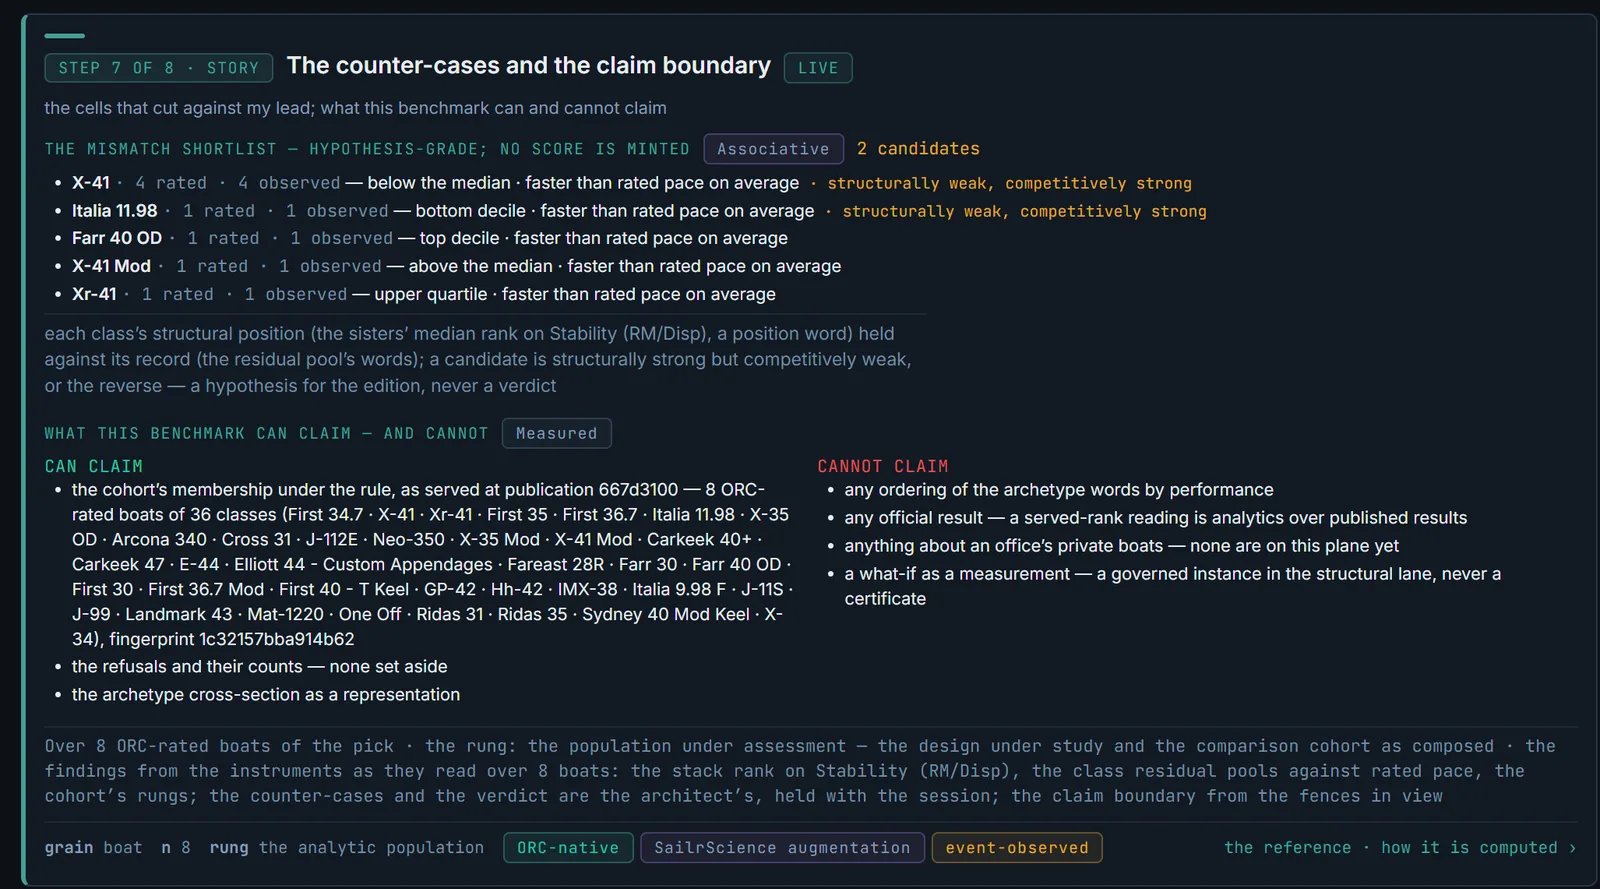
Three lead findings carry the story in the same ten fields — the read, the reference, the magnitude, the evidence, the composition, the agreement, the confidence, the counter-case, the claim boundary, the next test — and a lead composes into the edition only with its counter-case placed beneath it.
The edition.
Issued with its reference — the study’s own number and date — the counter-cases beneath each lead and the claim boundary carried whole. This study’s edition was not yet issued at the capture; the product’s rail says so, in its own words.
The study, and the edition.
Aggregate reads over the public corpus — the certificate each boat holds and the published results — every read carrying its source and its evidence level. There is no verdict between sources: you read the composition and draw the boundary.
The door
Name a boat, upload a certificate into the public intake, pick a design class or pick an event; the comparison proposed from her record and edited by hand; the question and the type of study declared.
The census
Who is in, who is set aside and why, what each measure can be read over — read before any map, with its source on every row.
The event’s conditions and entry record
An event the cohort shared, in place before any observed read: the races, the conditions, the gates; the official result never claimed.
The atlas
The five-axis read in words, the structural scatter, the stack rank against the comparison’s median, the archetype list as a representation — each an augmentation, named as one.
The certificate and the ledger
Up to four certificates side by side with the reference boat’s color; the variance ledger across a class’s sisters and the twin census beneath.
The observed record and race insights
Her corrected times against her rated pace, side by side, with the records and their confidence; the event race by race beside its conditions.
The composition and the agreement
Every read by source — augmentation, ORC-native, event-observed, marked as not published; two medians, one population; no verdict given between them.
The story and the edition
Three lead findings in ten fields, the counter-cases placed beneath, the claim boundary drawn; the edition issued with its reference.
What is available, layer by layer
Every screen carries its own mark — ready or waits, live, or marked as not published — and a panel’s mark governs its claims; the office’s private tier is planned and says so.
Built on the FleetEdge platform’s shared core, reading the public corpus at the certificate and the published record; every read names its reference and how it is computed.
Deliberately not here: a verdict between the certificate and a placement — you read the composition. No official result — a FleetEdge ranking is analytics over published results. No private tier yet — every screen shows the public corpus. No design is called better without its conditions attached, and the model’s internals stay internal.
Ask. Read. Verify. Tell. Issue.
For design offices and sail analysts who must say, and defend, what a design is worth — before a client consult, after a launch, across a range.
- Ask — name the subject, take or edit the comparison the product proposes, declare the question and the type of study.
- Read — the census, the event’s conditions and entry record, the atlas, the certificate, the observed record — each read with its source and its evidence level.
- Verify — the composition by source and the agreement under that record; no verdict where the product gives none.
- Tell — the lead findings in ten fields, the counter-cases placed, the claim boundary drawn.
- Issue — the edition with its reference, the boundary carried whole.
A note on the numbers above.
· Every figure on this page reads from the product screens pictured — the product’s own study on the public corpus, captured 9 September 2026 at the product’s publication of 3 September 2026.
· The counts in the screens are that capture’s own reads; this page restates none, and the words it uses for positions and directions are the product’s own at the capture.
· A FleetEdge ranking is analytics over published results; no official result is claimed on this page or in the product.
· The marks — ready, waits, live, “typed absent” (marked as not published) — are the product’s own vocabulary, declared panel by panel; a panel’s mark governs its claims.
· The office’s private tier is planned; every screen shows the public corpus, and the study is the product’s own demonstration, not an office’s work.
· No design is called better than another here — the product shows its work and draws its claim boundary.
· Beta access is by request.
Design Benchmarks draws on the FleetEdge taxonomy and hull layer: Fleet Archetypes, Hull & Platform, and the Methodology.
See it against your own work.
Scope: the public corpus today · the office’s private tier planned · in beta, access by request.